 ScrapeOps
Ian Kerins
Founder of ScrapeOps. Over 8 years in the web scraping market working with ScrapeOps, Zyte and ScraperAPI.
About Ian
Ian Kerins is the founder of ScrapeOps, the proxy aggregator and DevOps toolkit for web scraping. He has spent more than eight years in the web scraping industry, working on the proxy and data extraction side of the market at Zyte and ScraperAPI before starting ScrapeOps.
At ScrapeOps he leads the research behind the Proxy Benchmark and the cost-per-successful-request analysis used across the site, comparing Proxy APIs and residential providers on live performance data rather than advertised success rates.
He also hosts the r/WebScrapingInsider AMA series, where proxy providers, scraping API teams and browser tool builders answer questions from the community, and writes The Web Scraping Insider newsletter on proxy economics and anti-bot changes.
His writing focuses on what makes scrapers reliable in production: proxy selection, browser fingerprinting, session management and the real cost of getting usable data at scale.
Articles by Ian
Benchmarks
Live performance and price comparisons of Proxy APIs and residential providers.
Best Proxy Providers in 2026, Based on 9 Billion Pages per Month
No single provider wins every workload. Based on 9 billion pages per month across 60,000 domains, here's what each major proxy provider is actually best at.
Most "Stealth Browser" APIs Fail Browser Fingerprinting Tests [April 2026]
From Browserbase to Hyperbrowser, we tested all the best stealth browser APIs on the internet. Which ones are worth your time?
Most "Smart Proxy" Scraping APIs Fail Browser Fingerprinting Tests [January 2026]
From Bright Data to Zenrows, we tested all the best ones on the internet. Which ones are worth your time?
Insight Articles
Data-driven analysis of proxy pricing, performance and the cost of scraping.
What Is the Best Proxy Provider? The Data Says There Isn't One.
There is no universal best proxy provider. Benchmark data shows price barely predicts performance, and the winner changes by site and volume. The only way to find the best provider is to measure your own workload.
Scraping Shock: Why Web Data Is Getting Too Expensive to Scrape
Scraping Shock is reshaping web scraping economics. As proxies get cheaper, successful scraping gets more expensive. Learn why web data is getting too expensive to scrape.
The Proxy Paradox - How Cheaper Proxies Are Making Web Scraping More Expensive
How web scraping got harder, even as proxies got cheaper. The Proxy Paradox is reshaping the economics of web scraping.
The State of Web Scraping 2022
What are the biggest trends and developments in web scraping? What does 2022, likely have in store for web scraping?
AMA Insights
What scraping teams, proxy providers and tool builders told the community, organised by topic.
Bypassing DataDome, Akamai, Incapsula and Kasada: Lessons From a Reverse Engineer
Hyper Solutions' founder on reverse engineering DataDome, Akamai, Incapsula and Kasada, and what it takes to keep a bypass working at scale.
Is Web Scraping Legal? 9 Practical Lessons from Internet Law Professor Eric Goldman
An internet law professor explains how the CFAA, contracts, copyright and DMCA 1201 shape real scraping decisions about accounts, suppliers and data.
Why Diagnosis Beats More Stealth: Lessons From 7 Years of Reverse Engineering Anti-Bot Systems
Why diagnosing blocks, keeping sessions consistent and choosing complexity carefully beat adding stealth, from 7 years of reverse engineering anti-bots.
Inside a Web Scraping API Processing 10 Billion Pages a Month: What Actually Keeps the Data Flowing?
Why Scrape.do skips the browser on most requests, maintains sessions for hard targets, and worries most about responses that look fine but miss data.
Web Scraping Isn't a Proxy Problem Anymore
Inside the target-specific reputation, session management, browser identity and capacity economics that decide whether a scraper actually works.
Why There Is No Best Proxy Provider (And What You Are Actually Paying For)
Billions of requests through 50+ proxy providers show why the best provider changes by website, page type and volume, and what you are really paying for.
Your Browser Can Look Real and Still Look Fake
Inside the fingerprint populations, IP reputation, black-box testing and maintenance burden that decide whether a stealth browser survives production.
The Hardest Part of a Browser Agent Isn't Browsing. It's Knowing It Worked.
Inside the persistent identity, moving-target stealth and verification problems that decide whether a browser agent's actions ever add up to a finished task.
AI Isn't Replacing Scraper Engineering. It's Moving It.
Inside the silent data failures, session trust limits, browser-context execution and repair boundaries that decide if an AI-built scraper survives production.
Why Your "Perfect" Browser Fingerprint Still Gets Blocked
Why scraper detection is no longer about one bad fingerprint, but whether your fingerprint, IP, cookies and session behavior keep describing the same believable browser.
What Proxy Providers Don't Tell You About Residential Proxies
Inside the shared supply, real-time filtering and misleading metrics that determine whether a residential proxy network actually performs.
ScrapeOps News
Product launches, announcements and updates across ScrapeOps.
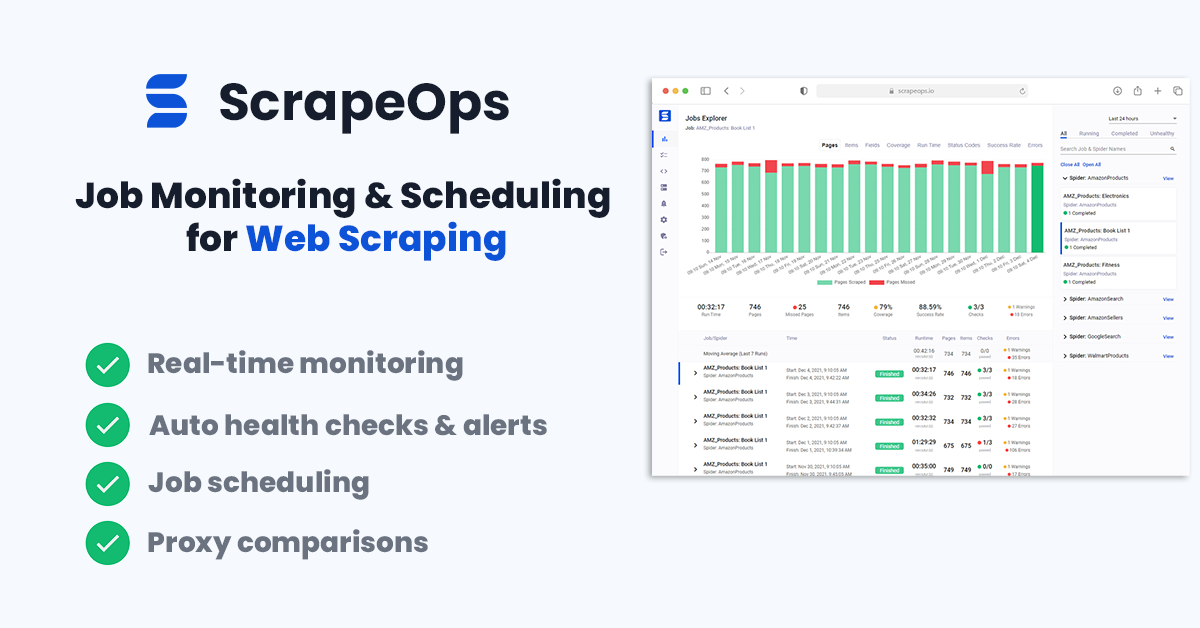
ScrapeOps - Job Monitoring, Alerts & Scheduling For Web Scrapers Made Simple!
Announcing the launch of ScrapeOps, a web scraping extension that gives you all the scraping monitoring, alerting, scheduling and data validation you need straight out of the box.
Launching The ScrapeOps Beta
Web Scraping Playbook
Free guides on scraping basics, anti-bot defenses, proxies, and the beginner series, plus benchmarks and field notes from production scraping.
We Tested 1,200 Free Proxies - Only ~2% Actually Worked (Here's the Data)
If you're considering using free proxies for any serious project, scraping, data collection, or anonymity then read on for our findings.
We Use 5 Different Methods to Scrape 82 Different Sites -- Here's Who Blocked Us (and Who Didn't)
Web scraping anti-bot defenses - What actually works? We tested 5 request methods across 82 websites, measuring block rates, CAPTCHAs, and JS challenges.
Web Scraping Market Report 2025
Web scraping market report 2025: Numbers, trends, and challenges shaping the industry. Insights for businesses, developers, and investors.
Web Scraping With Celery & RabbitMQ - How to Run Thousands of Scrapers Without Losing Your Mind
Learn to run thousands of scrapers with Celery and RabbitMQ. Set up robust task queues for scalable web scraping without losing your mind.
Why Y Combinator's Investments Reveal the Future of Web Scraping & AI
Why Y Combinator's investments reveal the future of web scraping and AI. Learn how YC backing suggests mainstream data extraction trends.

Web Scraping Guide Part 4: Handing Failed Requests and Using Concurrency with Python Requests/BS4 + Selenium, Puppeteer, Playwright & Axios
Web scraping guide part 4: Handle failed requests and use concurrency with Python Requests/BS4, Selenium, Cheerio, Puppeteer, and Playwright.
Web Scraping Part 3 - Storing Data in AWS S3, MySQL & Postgres DBs
Web scraping guide part 3: Store data in AWS S3, MySQL, and PostgreSQL databases. Learn pros, cons, and use cases for each storage method.

How To Bypass Anti-Bots in 2026
Learn how to bypass anti-bot protections like Cloudflare, DataDome, etc. so you can scrape protected websites.
Web Scraping Part 5 - Using Fake User-Agents and Browser Headers
In Part 5 of the series, we make our scraper production ready by managing our fake user-agents & browser headers to make our scrapers look more like real users
Web Scraping Part 6 - Using Proxies
Web scraping guide part 6: Use proxies to bypass website restrictions. Hide your IP address and location for successful web scraping.

Cloudflare Error 1015 - How To Bypass Rate Limiting
Learn to bypass Cloudflare Error 1015 rate limiting - use Puppeteer stealth mode, proxy rotation, fortified browsers, and smart proxy services for web scraping.
Cloudflare Error 1020 - How To Bypass Denied Access
Learn to solve Cloudflare error 1020 for web scrapers. Master strategies to bypass denied access and continue successful scraping.

Web Scraping Guide Part 2: Cleaning Dirty Data & Dealing With Edge Cases Using Python Requests/BS4 + Selenium, Puppeteer, Playwright & Axios
Web scraping guide part 2: Clean dirty data and handle edge cases with Python Requests/BS4, Selenium, Cheerio, Puppeteer, and Playwright.

How To Bypass DataDome in 2026 - The Complete Guide
A 2026 guide to bypassing DataDome's anti-bot protection — covering archive lookups, fortified headless browsers (undetected-chromedriver, nodriver, camoufox), TLS impersonation, smart proxy bypasses and the deeper detection internals.

Web Scraping Guide Part 1: Build Your First Scraper
In Part 1 of the series, we go over the basics of how to build a scraper using Python Requests & BS4, Selenium, Node.js Cheerio, Puppeteer, and Playwright.

How To Bypass PerimeterX in 2026
Learn how to bypass PerimeterX's anti-bot protection so you can reliably scrape PerimeterX protected websites.
How To Bypass Cloudflare When Web Scraping (2026)
Learn how to bypass Cloudflare anti-bot protection when web scraping — compare 8 methods (smart proxies, TLS impersonation, FlareSolverr, headless browsers) with benchmark results.

Differences of Web Scraping Vs Web Crawling Explained
Learn the differences between web scraping and web crawling, and how to combine them both.

How To Solve 403 Forbidden Errors When Web Scraping (2026)
A practical 2026 guide to fixing 403 Forbidden errors in Python, Scrapy and Node.js scrapers — covering user-agents, headers, proxies, TLS/JA3 fingerprinting and Cloudflare bypasses.
Where Do Residential & Mobile Proxies Come From?
Find where residential and mobile proxies come from. Learn the 5 main sources: VPNs, SDKs, bandwidth products, device farms, and reselling.
The Crazy Economics of Residential & Mobile Proxies
Explore the crazy economics of residential and mobile proxies. Learn how to build profitable proxy networks with SDKs and extensions.
The 5 Best Web Scraping Books 2023
Here are the 5 best web scraping books for 2023 that you can use to learn web scraping or take your skills to the next level.
Web Scraping Guide - Headers & User-Agents Optimization Checklist
Get your questions answered and stay up to date with the latest web scraping trends with these web scraping communities.
Web Scraping Without Getting Blocked
Learn how to scrape websites without getting blocked by CAPTCHAs, Bans, and other anti-bot protections.
Best Web Scraping Communities Everyone Should Know About
Get your questions answered and stay up to date with the latest web scraping trends with these web scraping communities.
The 7 Best Web Scraping SubReddits
Join one of the best web scraping subreddits to stay up to date on everything web scraping and get your questions answered.
The Best Web Scraping Discord Servers
Join one of the best web scraping discord servers to stay up to date on everything web scraping and get your questions answered.

Is Web Scraping Ethical?
Is web scraping unethical? The case for web scraping and the case against, and how to be an ethical web scraper.

Residential Proxies Explained - How You Can Scrape Without Getting Blocked
Residential proxies are proxies that use residential networks to scrape data, and have exploded in popularity over the last few years.

What Is Web Scraping? A Beginner's Guide On How To Get Started
Web scraping is a polarising topic, so in this guide we discuss everything you need to know about web scraping.
Python Web Scraping Playbook
Python scraping guides for Requests, HTML parsers, headless browsers, proxies, user-agents, logins, and choosing a library for the job.

How To Minimize Web Scraping Costs With Python
In this guide, we will dive into various approaches for minimizing web scraping costs with Python.

How To Submit Forms With Python Requests
In this guide, we will dive into various approaches for submitting forms using Python and provide detailed steps and examples for each method.
How To Download Images With Python
In this guide, we will explore various methods to download images using Python, offering detailed steps and examples for each approach.

How To Bypass Anti-Bots With Python
Learn Python methods to bypass anti-bot measures - optimize request fingerprints, rotate proxies, use fortified browsers, and reverse engineer protection systems.
How To Submit a Form With Python
In this guide, we will dive into various approaches for submitting forms using Python and provide detailed steps and examples for each method.

How To Solve CAPTCHAs with Python
Complete guide to solving CAPTCHAs with Python - learn Tesseract OCR, EasyOCR, 2Captcha API, anti-bot bypass, and legal considerations.

Fix SSL Errors in Python Requests
Fix Python Requests SSL errors - learn certificate validation, hostname verification, handshake failures, and best practices for SSL handling.

The Best Python Headless Browsers For Web Scraping in 2024
Discover the best Python headless browsers for web scraping in 2024. Compare Selenium, Playwright, Puppeteer, and ScrapeOps options.
How To Scroll Infinite Pages in Python
Learn to scroll infinite pages in Python for web scraping. Master Selenium, Requests, and ScrapeOps Headless Browser techniques.
Python hRequests - How to Send POST Requests
In this guide, we walk through how to send POST requests with Python Hrequests. Including how to POST form data and JSON data.
Python hRequests - Make Concurrent Requests
In this guide, we walk through how to configure Python hRequests to make concurrent requests so that you can increase the speed of your scrapers.
Python hRequests - Retry Failed Requests
In this guide, we walk through how to configure Python hRequests to retry failed requests so you can build a more reliable system.
Python hRequests - Setting Fake User-Agents
In this guide, we walk through how to use fake user-agents with Python Hrequests to prevent your scrapers from getting blocked.
Python hRequests - Web Scraping Guide
In this guide, we walk through how you should set up your Python Request scrapers to avoid getting blocked, retrying failed requests and scaling up with concurrency.

Python Selenium vs Python Pyppeteer Compared
Should you use Python Selenium or Python Pyppeteer? In this guide we compare both options and tell you when you should use each.
Python Scrapy vs Requests with Beautiful Soup Compared
In this article, we're going to explore two popular Python libraries—Scrapy and Requests with Beautiful Soup—and review their strengths, weaknesses, and use cases.
Python Scrapy vs Python Pyppeteer Compared
Should you use Python Scrapy or Python Pyppeteer? In this guide we compare both options and tell you when you should use each.
Python Selenium vs NodeJS Playwright Compared
Should you use Python Selenium or NodeJS Playwright? In this guide we compare both options and tell you when you should use each.
Python Scrapy VS Python Selenium Compared
Should you use Python Selenium or Python Scrapy? In this guide we compare both options and tell you when you should use each.
Python aiohttp - Setting Fake User-Agents
In this guide, we walk through how to use fake user-agents with Python aiohttp to prevent your scrapers from getting blocked.

Python Requests - Web Scraping Guide
In this guide, we walk through how you should set up your Python Request scrapers to avoid getting blocked, retrying failed requests and scaling up with concurrency.

Python aiohttp - How to Send POST Requests
In this guide, we walk through how to send POST requests with Python aiohttp. Including how to POST form data and JSON data.

Python HTTPX - How to Send POST Requests
In this guide, we walk through how to send POST requests with Python HTTPX. Including how to POST form data and JSON data.
Python HTTPX - Retry Failed Requests
In this guide, we walk through how to configure Python HTTPX to retry failed requests so you can build a more reliable system.
Python HTTPX - Setting Fake User-Agents
In this guide, we walk through how to use fake user-agents with Python HTTPX to prevent your scrapers from getting blocked.

Python Requests - Setting Fake User-Agents
In this guide, we walk through how to use fake user-agents with Python Requests to prevent your scrapers from getting blocked.

The 5 Best Python HTML Parsing Libraries Compared
We compare the 5 best Python HTML parsing libraries available in 2023 - BeautifulSoup, lxml, html5lib, requests-html, and pyquery.

Python Requests - How to Send POST Requests
In this guide, we walk through how to send POST requests with Python Requests. Including how to POST form data and JSON data.
Python Selenium VS Python Requests Compared
Should you use Python Selenium or Python Requests? In this guide we compare both options and tell you when you should use each.
FlareSolverr Guide - Bypassing Cloudflare With Python (2026)
A 2026 guide to installing and using FlareSolverr to bypass Cloudflare from Python — covering Docker setup, cookie-reuse strategies, sessions, POST requests and when to use a managed bypass instead.

How To Eliminate Span & Other HTML Tags With BeautifulSoup
In this guide, we walk through how to use BeautifulSoup to remove HTML tags like span, script, etc. from HTML files.
Python CloudScraper - Scrape Cloudflare Protected Websites
Learn to bypass Cloudflare protection with Python CloudScraper library - configure browser profiles, user-agents, proxies, and CAPTCHA solvers.
FeedParser Guide - Parse RSS, Atom & RDF Feeds With Python
In this guide, we walk through the Python FeedParser library and how to parse RSS, Atom & RDF feeds.
Newspaper3k Guide - Scrape Articles Using AI
In this guide, we walk through the Python Newspaper3k library and how to use it to scrape & curate articles.

How To Build A Python Web Scraping Framework
Learn how to build a Python scraper that will crawl Indeed.com for jobs and scrape jobs pages.

Fix BeautifulSoup Returns Empty List or Value
In this guide, we walk through how to fix your code when BeautifulSoup returns an empty list or value.
How To Install BeautifulSoup
In this guide, we walk through how to install and use BeautifulSoup on Windows, MacOS, and Linux machines.
How To Use BeautifulSoup's find_all() Method
In this guide, we walk through how to use BeautifulSoup's find_all() method to find a list of page elements by class, id, text, regex, and more.

How To Use BeautifulSoup's find() Method
In this guide, we walk through how to use BeautifulSoup's find_all() method to find the first page element by class, id, text, regex, and more.

BeautifulSoup Guide - Scraping HTML Pages With Python
In this guide, we walk through how to use BeautifulSoup to scrape data from HTML websites and files.

Parsel Guide - Scraping HTML Pages With Python
In this guide, we walk through how to use Parsel to scrape data from HTML websites and files.

Python Requests - How To Retry Failed Requests (2026 Guide)
A 2026 guide to retrying failed requests with Python Requests, tenacity, httpx and Retry-After headers — including session-level retry strategies, exponential backoff with jitter, and idempotency-aware retry logic.

Python Requests - Make Concurrent Requests
In this guide, we walk through how to configure Python Requests to make concurrent requests so that you can increase the speed of your scrapers.

The Python Pyppeteer Guide - Use Puppeteer With Python
In this guide we show you how to use Python Pyppeteer, the Puppeteer library for Python, to render and scrape Javascript heavy websites.

PycURL - Guide to Using cUrl With Python
In this guide, we walk through how to use cURL in Python using PycURL. Including how to make GET, POST requests, use proxies, user-agents, and more.

Python Fake User-Agents - How to Manage User Agents When Scraping
In this guide we show you how to create and manage fake user agents when scraping in Python so you don't get blocked.
Python aiohttp - How to Use & Rotate Proxies
Learn to use and rotate proxies with Python aiohttp. Master proxy gateways, APIs, and rotation strategies for async web scraping.
Python HTTPX - How to Use & Rotate Proxies
Learn to use and rotate proxies with Python HTTPX. Master proxy gateways, APIs, and rotation strategies for modern web scraping.

Python Requests - How to Use & Rotate Proxies
Learn to use and rotate proxies with Python Requests. Master proxy gateways, APIs, and rotation strategies for reliable web scraping.
Python Scrapy Playbook
Learn Scrapy from the first spider through crawling, items and pipelines, proxies, ban avoidance, and storing data at scale.

freeCodeCamp Scrapy Beginners Course Part 1 - Overview
The complete Scrapy beginners course. Learn everything you need to start scraping your first website at scale.

freeCodeCamp Scrapy Beginners Course Part 10 - Deploying & Scheduling Spiders With Scrapyd
Learn how to use Scrapyd to deploy and run your spiders in the cloud.

freeCodeCamp Scrapy Beginners Course Part 11 - Deploying & Scheduling Spiders With ScrapeOps
Learn how to deploy and schedule Scrapy spiders with ScrapeOps free scheduling tool.

freeCodeCamp Scrapy Beginners Course Part 12 - Deploying & Scheduling Spiders With Scrapy Cloud
Learn how to deploy and schedule Scrapy spiders with ScrapeOps free scheduling tool.

freeCodeCamp Scrapy Beginners Course Part 13 - Conclusion & Next Steps
Wrap up of the freeCodeCamp Scrapy Beginners Course & next steps for those who want to go deeper into Scrapy.

freeCodeCamp Scrapy Beginners Course Part 2 - Setting Up Scrapy
Part 2 of freeCodeCamp Scrapy course - learn to install Python, create virtual environments, install pip, and set up Scrapy on Windows, Mac, and Linux.

freeCodeCamp Scrapy Beginners Course Part 3 - Creating Scrapy Project
Part 3 of freeCodeCamp Scrapy course - learn to create Scrapy projects, understand spiders, items, middlewares, pipelines, and project structure for web scraping.

freeCodeCamp Scrapy Beginners Course Part 4 - First Scraper
Part 4 of freeCodeCamp Scrapy course - create your first Scrapy spider to scrape BooksToScrape.com, extract book data, and handle pagination with CSS selectors.

freeCodeCamp Scrapy Beginners Course Part 5 - Advanced Scraper
Part 5 of freeCodeCamp Scrapy course - build advanced scraper to crawl BooksToScrape.com, extract book data, use Scrapy Shell, and handle pagination.

freeCodeCamp Scrapy Beginners Course Part 6 - Items & Item Pipelines
Learn how to use Items and Item Pipelines to structure and clean your scraped data.

freeCodeCamp Scrapy Beginners Course Part 7 - Saving Data To Files & Databases
Learn how to save our scraped data to CSV files and MySQL & Postgres Databases

freeCodeCamp Scrapy Beginners Course Part 8 - Fake Headers & User Agents
Part 8 of freeCodeCamp Scrapy course - learn to use fake headers and user-agents, rotate them, and integrate ScrapeOps APIs to prevent blocking.

freeCodeCamp Scrapy Beginners Course Part 9 - Rotating Proxies & Proxy APIs
Learn how to use rotating proxies and proxy APIs with Scrapy.
The Scrapy Redis Guide - Scale Your Scraping With Distributed Scrapers
In this guide we show you how to use Scrapy Redis to run distributed crawls/scrapes across multiple servers and scale up your data processing pipelines.
Python Scrapy - Build A LinkedIn People Profile Scraper [2026]
Build a Python Scrapy spider to scrape LinkedIn profiles - extract names, descriptions, followers, experience, education, and bypass anti-bot protection.

Python Scrapy - Build A Amazon Products Scraper [2023]
Learn how to build a Python Scrapy spider that will crawl Amazon.com for products and scrape Amazon product pages.
Python Scrapy - Build A Amazon Reviews Scraper [2023]
Build a Python Scrapy spider to scrape Amazon reviews - extract ratings, review text, dates, helpful votes, and bypass anti-bot protection with proxy rotation.
Python Scrapy - Build A Indeed Scraper [2024]
Learn how to build a Python Scrapy spider that will crawl Indeed.com for jobs and scrape individual job pages.

Python Scrapy - Build A Walmart Scraper [2026]
Learn how to build a Python Scrapy spider that will crawl Walmart.com for products and scrape Walmart product pages.
Scrapy Login Guide - How To Login Into Any Website With Scrapy
In this guide, we through how to build a Scrapy spider that can log into any website and scrape private data.
Scrapy Cloud - Guide to Running Spiders In The Cloud
Learn how to deploy, schedule and run your Scrapy spiders in the cloud using Zyte's (formerly Scrapinghub's) Scrapy Cloud.
Scrapy Cloud - 3 Free & Cheap Alternatives
In this guide, we talk about the best free alternatives to Zyte's (formerly Scrapinghub's) Scrapy Cloud.
How To Set Scrapy Delays/Sleeps Between Requests
In this guide, you can configure delays between your requests using Scrapy's DOWNLOAD_DELAY and AutoThrottle extension.

How To Solve Scrapy 403 Unhandled or Forbidden Errors (2026)
A practical 2026 guide to fixing Scrapy 403 errors — covering settings.py changes, fake user-agents, request-header optimisation, rotating proxies, TLS fingerprinting and Cloudflare-protected targets.
How To Solve A Scrapy 503 Service Unavailable Error
In this guide, we walk through how to troubleshoot and solve Scrapy 503 Service Unavailable errors when web scraping or crawling.
Intro to Web Scraping With Scrapy
Complete guide to Scrapy web scraping framework - learn architecture, pros/cons, installation, and build your first spider with Python.

The 4 Best Scrapy Extensions to Render JS Heavy Websites
In this guide we will go through the best javascript rendering libraries for Scrapy so you can scrape modern websites with ease.
The Scrapy Selenium Guide
In this guide we show you how to setup and use Scrapy Selenium in your Spider to extract JS rendered data from webpages.
Mastering Scrapy Item Loaders - Streamlining Data Extraction and Formatting
In this guide, we will show you how to turn unstructured HTML data into clean and structured data that can be used in your applications and data pipelines.
Scrapy Items - The Better Way To Format Your Data
In this guide we show you how to use Scrapy Items to better organize & process your scraped data.
Scrapy Database Guide - Saving Data To CSV Files
In this guide we show you how to save the data you have scraped to a CSV file with Scrapy Feed Exporters.
Scrapy Database Guide - Saving Data To JSON Files
In this guide we show you how to save the data you have scraped to a JSON file with Scrapy Feed Exporters.
Scrapy Database Guide - Saving Data To MySQL Database
In this guide we show you how to save the data you have scraped to a MySQL database with Scrapy Pipelines.
Scrapy Database Guide - Saving Data To Postgres Database
In this guide we show you how to save the data you have scraped to a Postgres database with Scrapy Pipelines.
Scrapy Database Guide - Saving Data To SQLite Database
In this guide we show you how to save the data you have scraped to a SQLite database with Scrapy Pipelines.

Scrapy Fake User Agents - How to Manage User Agents When Scraping
In this guide we show you how to create and manage fake user agents when scraping so you don't get blocked.
Scrapy Proxies - How to Integrate & Rotate Proxies With Scrapy
In this guide we show you how you can easily start using proxies with your Scrapy spiders.
Scrapy Proxies - Waterfall Requests Over Multiple Proxies
In this guide we show you how you can build a custom proxy waterfall middleware that allows you to cut the cost of your proxies.

The Scrapy Playwright Guide
In this guide we show you how to use Scrapy Playwright to render and scrape Javascript heavy websites

The Scrapy Splash Guide
In this guide we show you how to setup and use Scrapy Splash in your Spider to extract JS rendered data from webpages.
Scrapy Beginners Series Part 3 - Storing Data With Scrapy
In Part 3 of the series, we explore several different ways we can store scraped data including CSV/JSON files, Amazon S3, MySQL & Postgres databases.
Scrapy Beginners Series Part 4 - User Agents and Proxies
In Part 4 of the series, we make sure our spiders are production ready by managing our user agents & proxies so we don't get blocked.
Build Your Own Custom Scrapy Middleware, Full Example
Learn to build custom Scrapy middleware for web scraping. Create downloader middleware, spider middleware, and item pipelines.

Build Your Own Custom Scrapy Middleware, Full Example
Learn to create custom Scrapy downloader middleware. Build your own proxy middleware and adapt it to your specific use case.
Scrapy Beginners Series Part 1 - First Scrapy Spider
Part 1 of Scrapy beginner series - learn basics, setup Python environment, create first spider, use Scrapy Shell, and handle pagination.
Scrapy Beginners Series Part 2 - Cleaning & Processing Data
In Part 2 of the series, we will make our spider robust to data quality edge cases, using Items, Itemloaders and Item Pipelines.
Scrapy Pagination Guide, The 6 Most Popular Pagination Methods
In this guide, we explain 6 of the most common pagination methods websites use and how to design your Scrapy spider to deal with them..
The 5 Best Scrapyd Dashboards & Admin Tools
In this guide we show you the 5 best Scrapyd dashboards, UIs and admin tools that you can manage your Scrapyd servers with.
The Complete Guide To ScrapydWeb, Get Setup In 3 Minutes!
In this guide, we explain everything you need to know about ScrapydWeb, how to get setup and running your spiders.
The Scrapyd Guide - Deploy & Schedule Your Scrapy Spiders
In this guide, we explain everything you need to know about Scrapyd, how to get setup, run and manage your spiders.
How to Monitor Your Scrapy Spiders!
Monitoring your scrapers performance in production is critical, in this guide we show you the best ways to monitor your Scrapy spiders.
The Complete Guide To Scrapy Spidermon, Start Monitoring in 60 Seconds!
In this guide, we explain everything you need to know about Spidermon and how to use it to monitor your Scrapy projects.
Node.js Web Scraping Playbook
Node.js guides for parsing HTML, headless browsers, proxies, user-agents, logins, and sending requests without getting blocked.
Best NodeJS Stealth & Bypassing Solutions
This guide will explore various strategies that can be used to bypass such defenses using NodeJS.
How To Bypass Anti-Bots With NodeJS
This guide will outline various methods for bypassing anti-bot measures during web scraping using NodeJS.
How to Download Images with NodeJS
In this guide, we will dive into various approaches for downloading images using NodeJS and provide detailed steps and examples for each method.

How to Scroll a Page with NodeJS
In this article, we'll walk through the scrolling techniques using Puppeteer and Playwright.

How To Submit a Form With NodeJS
In this guide, we will dive into various approaches for submitting forms using NodeJS and provide detailed steps and examples for each method.
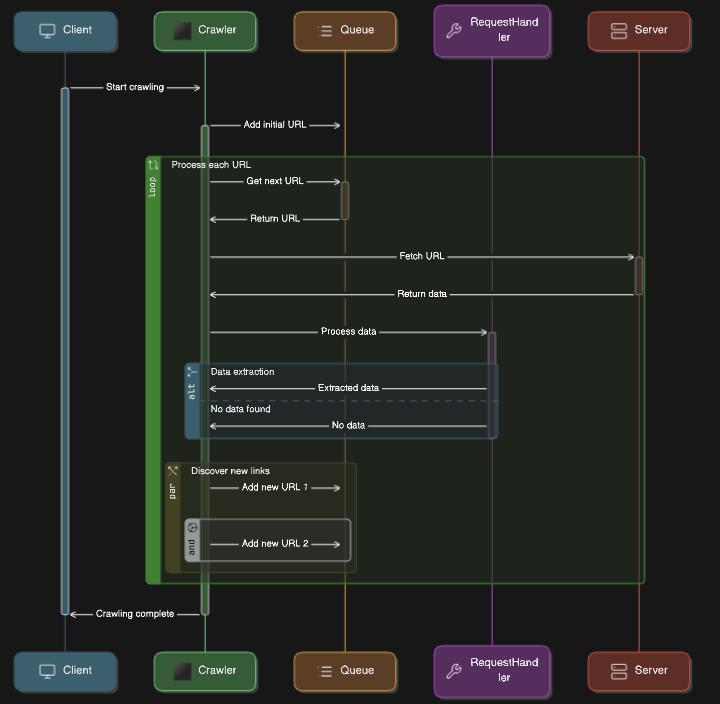
NodeJS Crawlee - Web Scraping Guide
In this guide, we cover a range of topics from the basic setup, through to advanced techniques, and strategies for deployment using NodeJS Crawlee.
How To Minimize Web Scraping Costs With Node.js
In this guide, we will dive into various approaches for minimizing web scraping costs with Node.js.
How To Solve CAPTCHAs with NodeJS
In this guide, we will explore various strategies and techniques for efficiently bypassing CAPTCHA challenges with NodeJS.
CheerioJS Guide - Scraping HTML Pages With NodeJs
Extract data from HTML pages with CheerioJS in Node.js. Learn efficient data parsing and manipulation techniques for web scraping.

The Best Node.js Headless Browsers for Web Scraping
In this guide, we will cover the top Node.js headless browsers used for web scraping today, explaining their key features and providing code examples.
Got, Fetch, Axios, SuperAgent - Retry Failed Requests
Guide to setting up retries for failed requests using Got, Node Fetch, Axios, SuperAgent & Request-Promise to build a more reliable NodeJS system.
Node-Fetch, Axios, SuperAgent, Got, Request-Promise - Make Concurrent Requests
Learn to configure Node-Fetch, Axios, SuperAgent, Request-Promise & Got to make concurrent requests and boost the speed of your scrapers.

The 5 Best NodeJS HTML Parsing Libraries Compared
We compare the 5 best NodeJS HTML parsing libraries available in 2023 - Cheerio, JSDOM, Parse5, htmlparser2, and xml2js.
Node.js (Got, SuperAgent, Axios & More) - How to Send POST Requests
Learn how to send POST requests with Node.js libraries: Got, SuperAgent, Node-Fetch, Axios, and Request Promise, including posting form data and JSON.
NodeJS Fake User-Agents - How to Manage User Agents When Scraping
In this guide we show you how to create and manage fake user agents when scraping in NodeJS so you don't get blocked.
NodeJs Proxy Rotation - How to Use & Rotate Proxies
Learn proxy use in Node-Fetch, Got, Request-Promise, Axios & SuperAgent. Rotate proxies, use gateways & scrape APIs with Node.js

Node Unblocker - Build Your Own Proxy Server
Node Unblocker is an open source library that allows you to easily build and deploy your own proxy server as a VPN or for web scraping.
Selenium Web Scraping Playbook
Selenium guides for finding elements, pagination, cookies, proxies, user-agents, and making a browser harder to detect while scraping.
How to Scrape Linkedin Profiles With Selenium
Learn to scrape LinkedIn profiles with Python Selenium. Extract profile data and bypass anti-bot protection with stealth techniques.

Python Selenium - How To Make Selenium Undetectable
Learn how to make Selenium undetectable with stealth techniques, undetected-chromedriver, proxy rotation, and anti-bot bypass methods for web scraping.

Python Selenium Guide - How To Take Screenshots
Learn to take screenshots with Python Selenium for web automation. Master screenshot techniques for debugging and documentation.

Python Selenium Guide - Finding Elements by CSS Selectors
In this comprehensive guide, we will demystify the art of locating HTML elements using CSS Selectors with Selenium.
Python Selenium Guide - How to Block Images and Resources
Blocking unnecessary resources, such as images, can enhance test performance by speeding up page loading and minimizing data usage.

Python Selenium Guide - How to Capture Background XHR Requests
The web apps rely on background XHR requests to load content. In this article, we'll explore why you need to capture them, how to capture them with Selenium.

Python Selenium Guide - How To Scroll The Page
The ability to navigate through a page, especially one with lazy-loaded or infinite-scrolling content, is crucial for comprehensive data extraction and interaction.

Python Selenium Guide - How To Use Selenium Stealth For Web Scraping
Selenium Stealth is a powerful tool designed to augment Selenium's capabilities for web scraping by adding an extra layer of anonymity.

Python Selenium Guide - Run Selenium Using a Jupyter Notebook
In this article, we will embark on a journey to explore the capabilities and applications of Jupyter Notebook using Selenium.

Python Selenium Guide - Downloading a File
In this guide, we will walk you through the process of downloading a file using Selenium.
Selenium Error - ChromeDriver Executable Needs to Be in PATH
In this article, we'll delve into the causes of ChromeDriver Executable Needs to Be in PATH error and explore effective solutions to resolve it.

Python Selenium Guide - How to Bypass Cloudflare with Selenium
Learn to bypass Cloudflare protection with Python Selenium. Master anti-scraping measures and practical solutions for web automation.

Python Selenium Guide - Submitting Forms with Selenium
Learn to submit forms with Python Selenium. Master form interactions, data input, and best practices for web automation and scraping.

Selenium Error - Geckodriver Executable Needs to Be in PATH
In this article, we'll delve into the causes of Geckodriver Executable Needs to Be in PATH error and explore effective solutions to resolve it.

Python Selenium Guide - How to Bypass Datadome with Selenium
Learn to bypass DataDome protection with Python Selenium. Master anti-scraping measures and practical solutions for web automation.
Python Selenium Guide - How to Bypass PerimeterX with Selenium
Learn to bypass PerimeterX protection with Python Selenium. Master anti-scraping measures and practical solutions for web automation.

Python Selenium Guide - Managing Cookies
Learn how to handle cookies with Selenium. Get, set, edit and delete cookies from your Selenium scraper.

Python Selenium Guide - Using Fake User Agents
In this guide, we'll explore the fake user agents, their implementation in Selenium scripts and provide practical insights to elevate your web scraping endeavors.

Python Selenium Guide - How To Find Elements by XPath
XPath is an extremely powerful tool for locating elements. In this guide we will deep dive into using XPath to find elements in Selenium.

Python Selenium Guide - Waiting For Page or Element To Load
Learn to wait for pages and elements to load with Python Selenium. Master timing strategies for reliable web automation and scraping.
The Python Selenium Guide - Web Scraping With Selenium
In this guide we show you how to use Python Selenium to render, automate and scrape Javascript heavy websites.

The Python Selenium Guide - Web Scraping With Selenium
In this guide we show you how to use Python Selenium to render, automate and scrape Javascript heavy websites.

Selenium Wire - Extending Python Selenium
In this guide, we walk through Selenium Wire a extension for Python Selenium that gives you more control over requests & responses.

Selenium Undetected Chromedriver - Bypass Anti-Bots With Ease
In this guide, we walk through how to setup and use Python Selenium's Undetected Chromedriver to bypass anti-bot solutions like Cloudflare, DataDome, etc.
Disable Images Loading In Python Selenium
In this guide, we walk through how to disable Python Selenium from loading images to speed up your scrapers and reduce bandwidth usage.

Using Proxies With Python Selenium (2026 Guide)
A 2026 guide to using HTTP, authenticated and rotating proxies with Python Selenium — covering Selenium 4 syntax, the Chrome extension approach for authenticated proxies, and TLS fingerprinting.
Puppeteer Web Scraping Playbook
Puppeteer guides for scraping JavaScript sites: extracting data, navigation, cookies, environments, and getting past anti-bot checks.
How to Scrape Bing With Puppeteer
In this guide, we'll take you through how to scrape Bing using Puppeteer.
How to Scrape Quora With Puppeteer
In this guide, we'll take you through how to scrape Quora using Puppeteer.
How to Scrape Target With Puppeteer
In this guide, we'll take you through how to scrape Target using Puppeteer.
How to Scrape Walmart With Puppeteer
In this guide, we'll take you through how to scrape Walmart using Puppeteer.
How to Scrape Indeed With Puppeteer
Learn to scrape Indeed job listings with Puppeteer. Extract job data, bypass anti-bot protection with stealth mode and proxies.
How To Make Puppeteer Undetectable
In this guide, we’ll explore how to overcome this limitation by making adjustments and applying patches to render Puppeteer undetectable to bot detectors.
How to Scrape G2 With Puppeteer
In this guide, we'll take you through how to scrape G2 using Puppeteer.
Puppeteer Real Browser Guide
In this guide, we will walk you through using Puppeteer Real Browser, which is designed to help you overcome bot detection and CAPTCHA challenges in web scraping.
Puppeteer Guide - How To Bypass Cloudflare with Puppeteer
In this guide, we show you how to use Puppeteer Extra and its plugins, including the best plugins for web scraping as well as advanced integrations
Puppeteer Guide - How to Bypass DataDome with Puppeteer
In this article, we'll explore how Puppeteer can be utilized to bypass DataDome's security defenses.
Puppeteer Guide - How to Bypass PerimeterX with Puppeteer
In this article, we'll explore how Puppeteer can be utilized to bypass PerimeterX's security defenses.

Puppeteer Guide - How To Find Elements by XPath
In this guide, we'll explore how to precisely locate and interact with DOM elements using XPath in Puppeteer.
Puppeteer Guide - Downloading A File
In this guide, we'll delve into various methods for downloading files from websites using Puppeteer.

Puppeteer Guide - Submitting A Form
In this guide, we'll cover various form input types and capturing responses after form submission using Puppeteer.
Puppeteer Guide - Run Using Jupyter Notebook
Run Puppeteer in Jupyter Notebook for interactive web scraping. Learn setup, code execution, and visualization for data analysis projects.

Puppeteer Guide - How to Capture Background XHR Requests
Blocking unnecessary resources, such as images, can enhance test performance by speeding up page loading and minimizing data usage.
Puppeteer Guide - How to Scroll Pages
Learn to scroll pages with Puppeteer for web scraping. Master various scrolling techniques for dynamic content and infinite scroll pages.
Puppeteer Guide - Using Fake User Agents
Learn to use fake user agents with Puppeteer. Emulate different browsers and devices to bypass detection and access device-specific content.

Puppeteer Guide - How to Find Elements by CSS Selectors with Puppeteer
In this comprehensive guide, we'll delve into the art of finding elements using CSS selectors with Puppeteer.

Puppeteer Guide - Managing Cookies
Learn to manage cookies with Puppeteer for web automation and scraping. Master cookie handling for effective browser automation.
Puppeteer Guide - How to Block Images and Resources using Puppeteer
In this guide, we'll cover the essential steps to selectively block the loading of images and other resources using Puppeteer.

Puppeteer Guide - Waiting For Page or Element To Load
Learn to wait for pages and elements to load with Puppeteer. Master timing strategies for reliable web automation and scraping.

How To Optimize Puppeteer for Web Scraping
In this guide, we show you how to optimize Puppeteer for web scraping, incorporating efficient configurations, best practices, and strategic implementation.
Puppeteer Guide - How To Take Screenshots
In this guide, we will explore how to capture web page screenshots efficiently using Puppeteer.

Puppeteer-Extra-Stealth Guide - Bypass Anti-Bots With Ease
In this guide, we will introduce the Puppeteer-Extra-Stealth Plugin, helps users bypass bot-detection systems.
Bypass CAPTCHAs With Puppeteer
Learn to bypass CAPTCHAs with Puppeteer - solve text, reCAPTCHA, hCAPTCHA, audio CAPTCHAs using 2Captcha API and avoid triggering them with stealth techniques.
What is Puppeteer Extra - A Web Scrapers Guide
Learn to use Puppeteer Extra and its plugins for web scraping. Discover the best plugins for debugging, stealth, and advanced integrations.
NodeJS Puppeteer - Logging Into Websites
In this guide, we walk through how to login to websites with NodeJS Puppeteer. Including, dealing with anti-bots and CAPTCHAs.
The NodeJS Puppeteer Guide
Learn to use Puppeteer for web automation in Node.js. Master the high-level API for automating tasks and interacting with dynamic web pages.
Using Proxies With NodeJS Puppeteer
In this guide, we walk through how to use proxies with NodeJS Puppeteer.
Playwright Web Scraping Playbook
Playwright guides for scraping rendered pages: selectors, navigation, cookies, browser setup, and bypassing common anti-bot systems.

How To Make Playwright Undetectable
In this guide, we’ll explore how to overcome this limitation by making adjustments and applying patches to render Playwright undetectable to bot detectors.

Playwright Guide - Waiting For Page or Element To Load
Learn to wait for pages and elements to load with Playwright. Master timing strategies for reliable web automation and scraping.

Playwright Guide - How to Bypass PerimeterX with Playwright
In this article, we'll explore how Playwright can be utilized to bypass PerimeterX's security defenses.

Playwright Guide - How To Find Elements by XPath
In this guide, we're going to learn how to find elements using their XPath selector.

Playwright Guide - Run Using Jupyter Notebook
Run Playwright in Jupyter Notebook for interactive web scraping. Learn setup, code execution, and visualization for data analysis projects.
Playwright Guide - How To Find Elements by XPath
Learn to find elements with XPath selectors in Playwright - master XPath syntax, locate elements by text, attributes, position, and handle dynamic content for web scraping.

Playwright Guide - Downloading A File
In this guide, we cover everything from finding elements on the page to finding URLs with Playwright.

Playwright Guide - How To Find Elements by CSS Selector
In this guide, we're going to learn how to find elements using their CSS selector.

Playwright Guide - How to Bypass DataDome with Playwright
Learn how to bypass DataDome protection with Playwright. Comprehensive guide for developers to automate browser interactions and extract data.

Playwright Guide - Submitting Forms
Learn to submit forms with Playwright. Master form interactions, dynamic inputs, and form validation for web automation and scraping.

Playwright Guide - Using Fake User Agents
Learn to use fake user agents with Playwright. Bypass bot detection and access user agent-specific content with custom user agents.

Playwright Guide - How To Bypass Cloudflare with Playwright
Learn how to bypass Cloudflare protection with Playwright. Comprehensive guide for developers and data analysts to automate browser interactions.

Playwright Guide - Managing Cookies
This guide covers how to get, set, modify, and delete cookies using Playwright's APIs. It also provides tips for handling cookies in real-world automation scenarios.

Playwright Guide - How to Scroll Pages with Playwright
Learn to scroll pages effectively with Playwright. Master scrolling functionality to enhance your web automation scripts and scraping projects.

Playwright Guide - Capturing Background XHR Requests
Learn to capture background XHR requests with Playwright. Block requests, identify endpoints, and enhance your web scraping toolbox.

Playwright Guide - How To Block Images and Resources
Optimize Playwright performance by blocking images and resources. Learn how to fine-tune your scraping project to load only required content.

NodeJS Playwright Guide - How To Take Screenshots
Learn to capture web page screenshots with Playwright - full page, element-specific, PDF generation, and advanced screenshot techniques for web scraping automation.

What is Playwright Extra - A Web Scrapers Guide
In this guide, we show you how to use Playwright Extra and its plugins, including the best plugins for web scraping as well as advanced integrations

NodeJS Playwright - Logging Into Websites
In this guide, we walk through how to login to websites with NodeJS Playwright. Including, dealing with anti-bots and CAPTCHAs.

The NodeJS Playwright Guide
In this guide, we’ll introduce you to the fundamental functionality of Node.js Playwright and how to use it in your own projects.

Using Proxies With NodeJS Playwright
Learn to use proxies with NodeJS Playwright - integrate HTTP proxies, authenticated proxies, proxy APIs, and bypass anti-bot protection for web scraping automation.
Java Web Scraping Playbook
Java scraping guides using OkHttp and Apache HttpClient, from sending requests to reading the HTML those clients return.
Java - How to Send POST Requests With Apache HttpClient & OKHttp
In this guide, we walk through how to send POST requests with Java using two popular libraries: Apache HttpClient and OKHttp. Including how to POST form data and JSON data.
Java Apache HttpClient - Retry Failed Requests
In this guide, we walk through how to configure Java Apache HttpClient to retry failed requests so you can build a more reliable system.
Java OkHttp & Apache HttpClient - Setting Fake User-Agents
How to use fake user-agents with Java OkHttp & Apache HttpClient Library to avoid your scrapers from getting blocked.
Java OkHttp & Apache HttpClient Library - How to Use & Rotate Proxies
In this guide, we walk through how to use proxies with Java OkHttp & Apache HttpClient Library. Including how to rotate proxies in a list, use proxy gateways, and proxy APIs with our Java OkHttp & Apache HttpClient scraper.
Java OkHttp & Apache HttpClient Library - Make Concurrent Requests
In this guide, we walk through how to configure Java OkHttp & Apache HttpClient Library to make concurrent requests so that you can increase the speed of your scrapers.

Java OkHttp - Retry Failed Requests
In this guide, we walk through how to configure Java OkHttp Library to retry failed requests so you can build a more reliable system.
Golang Web Scraping Playbook
Go scraping guides for proxy rotation, user-agents, and reducing blocks, with Colly examples from this playbook you can adapt.
Go Colly Use Random Fake User-Agents When Scraping
In this guide we show you how to use random fake user agents when scraping with Golang Colly so you don't get blocked.

Golang Colly - How to Use & Rotate Proxies
In this guide, we walk through how to use proxies with Go Colly. Including how to rotate proxies in a list, use proxy gateways, and proxy APIs with our Go Colly.
Pyppeteer Web Scraping Playbook
Use Pyppeteer to run Puppeteer-style browser automation in Python, with guides for rendered pages and how it compares with Node.js tools.
C# Web Scraping Playbook
Guides for scraping the web with C# and .NET, including how to send requests and work with the HTML those requests return.
Proxy economics, anti-bot news and AMA recaps
One email per issue. Unsubscribe anytime.