 ScrapeOps
Python Selenium Guide - Finding Elements by CSS Selectors
 Selenium Web Scraping Playbook11 min read

CSS Selectors provide a powerful and flexible way to pinpoint elements, enabling precise interactions in your browser automation scripts.
In this comprehensive guide, we will demystify the art of locating HTML elements using CSS Selectors with Selenium.
TLDR: How to Select Elements by CSS with Selenium
When selecting elements with CSS in Selenium, we use Selenium's single find_element() method or multiple find_elements() method. Take a look below to see this in action.
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom time import sleep#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com")#find the h1 elementh1 = driver.find_element(By.CSS_SELECTOR, "h1")#print the h1 elementprint(f"H1 element: {h1.text}")#find all quotes (span elements with the class: 'text')quotes = driver.find_elements(By.CSS_SELECTOR, "span[class='text']")for quote in quotes: print(f"Quote: {quote.text}")#find all tags (anything with the class 'tag')tags = driver.find_elements(By.CSS_SELECTOR, ".tag")for tag in tags: print(f"Tag: {tag.text}")#find the login link (first a element with href: '/login/')login_link = driver.find_element(By.CSS_SELECTOR, "a[href='/login/']")login_link.click()#find the username box (element with ID: 'username')username = driver.find_element(By.CSS_SELECTOR, "#username")username.send_keys("some text")#find the password box (input elements with the type: 'password')password = driver.find_element(By.CSS_SELECTOR, "input[type='password']")password.send_keys("my super secret password")#sleep 5 seconds so the user can see the filled input boxessleep(5)driver.quit()| Method | Description |
|---|---|
find_element(By.CSS_SELECTOR, "my_selector") | Finds the first element that matches. If no element matches the selector, a NoSuchElementException will be raised. |
find_elements(By.CSS_SELECTOR, "my_selector") | Finds all elements that match the CSS selector and return them in a list, returns an empty list if no element is found. |
CSS Selectors Demystified
Cascading Style Sheets (CSS) is a layout for styling webpages written in HTML. When styling with CSS, developers use certain selectors to target specific items on a webpage.
For instance, if we make a custom CSS class and name it our-custom-class, our CSS may look like this:
.our-custom-class { background: black; /*set the background to black*/ padding-right: 24px; /*24 pixels of padding on the sides*/ color: white; /*set the font color to white*/ height: 100vh; /*vh means viewport height---set the height to 100% of the viewport */ display: flex; /*use a flex display for elements within this element*/ justify-content: center; /*put content in the center*/ align-items: center; /*align nested items to the center of this element */}Now let's add an HTML page that links to our CSS page:
<!DOCTYPE html><html> <head> <meta charset="UTF-8"> <title>Our Demo Page</title> <link rel="stylesheet" type="text/css" href="demo.css"> </head> <body> <h1>Some Words</h1> <p>These are some smaller words.</p> </body></html>If we open the page in our browser, it will look like the image below:
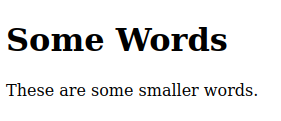 Plain HTML page
Now let's add our class to our body element:
<!DOCTYPE html><html> <head> <meta charset="UTF-8"> <title>Our Demo Page</title> <link rel="stylesheet" type="text/css" href="demo.css"> </head> <body class="our-custom-class"> <h1>Some Words</h1> <p>These are some smaller words.</p> </body></html>Now that we've styled the element, it looks like this:
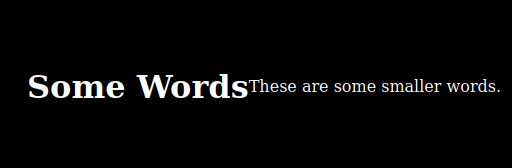 HTML Page Styled with CSS
When searching for CSS selectors on an existing page, we can search and select items with the following criteria:
- Tag Name
- ID
- Class
- Attribute
- Descendant
- Child
- Adjacent Sibling
- General Sibling
- Pseudo-class
- Pseudo-element
| Selector Type | CSS Syntax | Description |
|---|---|---|
| Tag Name | tag | Selects elements by their tag. |
| ID | #id | Selects an element by its ID. |
| Class | .class | Selects elements by their class. |
| Attribute | [attribute=value] | Selects elements with a specific attribute. |
| Descendant | ancestor descendant | Selects an element within another element. |
| Child | parent > child | Selects direct children of an element. |
| Adjacent Sibling | previous + next | Selects an element directly after another. |
| General Sibling | sibling ~ sibling | Selects all siblings of a specified element. |
| Pseudo-class | element:pseudo-class | Selects elements in a certain state. |
| Pseudo-element | element::pseudo-element (Rare in Selenium, as Selenium focuses on the DOM structure, not rendering). | Selects specific parts of an element. |
Finding CSS Selectors
To find CSS Selectors on a page, first we must inspect the page through the developer console. Simply right-click the element and choose to copy the CSS selector:
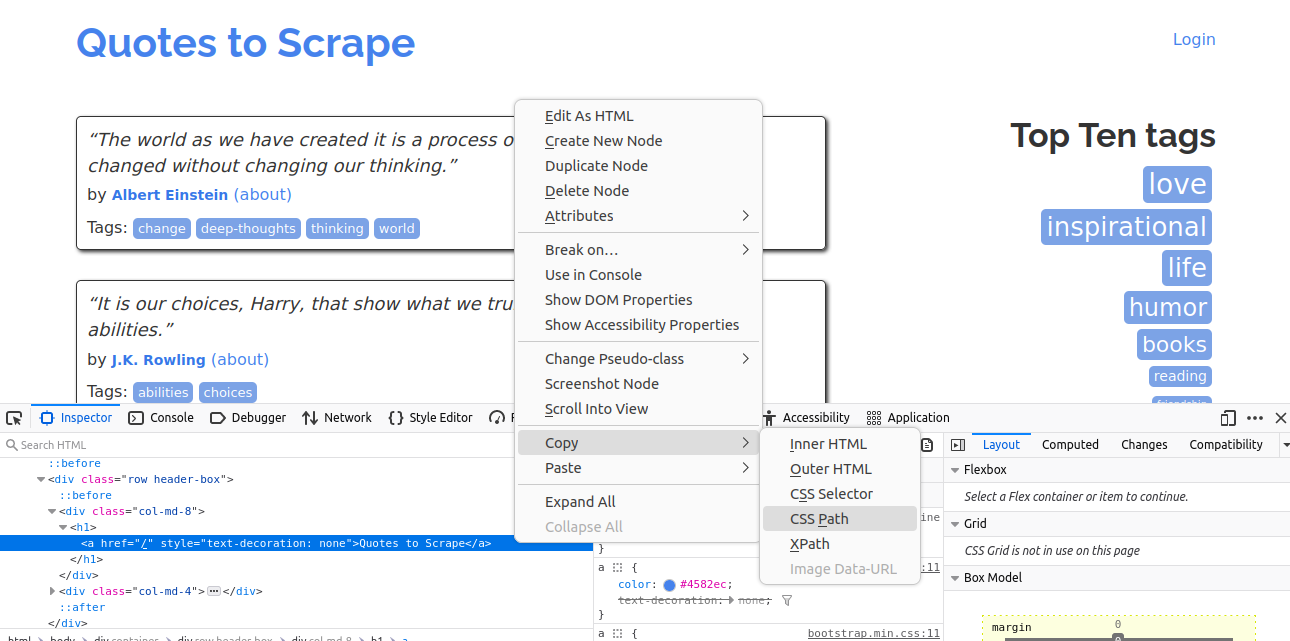 Copy CSS Quotes to Scrape
Finding One Element Using CSS Selector
If we'd like to find just one element, we can use Selenium's find_element() method to find and return a single element. The code below finds a single element and prints its text to the terminal.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open an instance of Chromedriver = webdriver.Chrome()#navigate to the pagedriver.get("https://quotes.toscrape.com")#selector for the h1 elementselector = "h1"#find element with this selectorelement = driver.find_element(By.CSS_SELECTOR, selector)#print the text of the elementprint(element.text)#close the browserdriver.quit()In the code above, we:
- Open Chrome with
webdriver.Chrome() - Navigate to the page with
driver.get() - Create a selector:
"h1" - Find the element with
driver.find_element() - Print the text of the element to the terminal
- Close the browser with
driver.quit()
Finding All Elements Using CSS Selector
Now that we have a basic understanding of CSS selectors, let's apply this new knowledge. The code example below finds all tag elements on the page.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open an instance of Chromedriver = webdriver.Chrome()#navigate to the pagedriver.get("https://quotes.toscrape.com")#look for custom elements named "tag"selector = ".tag"#find all elements with this selectorelements = driver.find_elements(By.CSS_SELECTOR, selector)#print the text of each elementfor element in elements: print(element.text)#close the browserdriver.quit()In the code above, we:
- Open an instance of Chrome with
webdriver.Chrome() - Navigate to the page with
driver.get() - Create a custom selector,
".tag" - Find all
.tagelements withdriver.find_elements()and return them in a list - Print the text of each list to the terminal
- CLose the browser with
driver.quit()
Explicit Wait: Using WebDriverWait with CSS Selectors
When interacting with dynamic elements, it is imperative that we use proper waiting strategies. Sometimes elements will not be interactable until we're hovering over them, sometimes elements won't be visble until we perform a certain action.
If we don't properly wait for these things to happen, Selenium will throw an exception and our scraper will crash.
Wait Until an Element is Present
In this section, we'll wait until an element is present and then find the element. In the example below, we find the menu button on the screen and then click on it.
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom selenium.webdriver.common.action_chains import ActionChainsfrom selenium.webdriver.support.ui import WebDriverWaitfrom selenium.webdriver.support import expected_conditions as EC#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://espn.com")#id selector for the menu buttonselector = "#global-nav-mobile-trigger"#create an ActionChains objectactions = ActionChains(driver)#wait until the menu button appearsopen_menu = WebDriverWait(driver, 5).until( EC.presence_of_element_located(( By.CSS_SELECTOR, selector)))#perform a chain of actionsactions\ .move_to_element(open_menu)\ .click()\ .perform()#close the browserdriver.quit()In the example above, we:
- Open Chrome
- Navigate to the site
- Use
WebDriverWaitto wait for the menu button to appear - Create an
ActionChainthat clicks on the menu button - Close the browser
Wait Until an Element is Visible
This code builds on our previous example and makes sure to find the menu after we've clicked on it and it is now visible.
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom selenium.webdriver.common.action_chains import ActionChainsfrom selenium.webdriver.support.ui import WebDriverWaitfrom selenium.webdriver.support import expected_conditions as EC#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://espn.com")#id selector for the menu buttonselector = "#global-nav-mobile-trigger"#create an ActionChains objectactions = ActionChains(driver)#wait until the menu button appearsopen_menu = WebDriverWait(driver, 5).until( EC.presence_of_element_located(( By.CSS_SELECTOR, selector)))#perform a chain of actionsactions\ .move_to_element(open_menu)\ .click()\ .perform()#id selector for the menu that appearsmenu_selector = "#global-nav-mobile"#wait until the menu appearsmenu = WebDriverWait(driver, 10).until( EC.presence_of_element_located(( By.CSS_SELECTOR, menu_selector )))#print the contents of the menuprint(menu.text)#close the browserdriver.quit()In the code example above, we:
- Create an instance of Chrome
- Navigate to the site
- Create a selector for the menu button with
selector = "#global-nav-mobile-trigger" - Wait for the element to appear with
WebDriverWait - Perform a chain of actions to
move_to_element(open_menu).click().perform() - Use another instance of
WebDriverWaitfor the actual menu to appear - Print the contents of the menu to the terminal
- Close the browser
Wait Until an Element is Clickable
In the previous example, if we were to click any of the menu items, we could get an exception because the element is not interactable. Most often, when these types of errors happen, it is because we need to hold the cursor over whichever element we're trying to select.
The following example builds on top of the previous two, and we'll use ActionChains to accomplish our task. First we'll find the element we want to click, then we'll move to the element, and click on it.
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom selenium.webdriver.common.action_chains import ActionChainsfrom selenium.webdriver.support.ui import WebDriverWaitfrom selenium.webdriver.support import expected_conditions as EC#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://espn.com")#id selector for the menu buttonselector = "#global-nav-mobile-trigger"#create an ActionChains objectactions = ActionChains(driver)#wait until the menu button appearsopen_menu = WebDriverWait(driver, 5).until( EC.presence_of_element_located(( By.CSS_SELECTOR, selector)))#perform a chain of actionsactions\ .move_to_element(open_menu)\ .click()\ .perform()#id selector for the menu that appearsmenu_selector = "#global-nav-mobile"#wait until the menu appearsmenu = WebDriverWait(driver, 10).until( EC.presence_of_element_located(( By.CSS_SELECTOR, menu_selector )))#css selector for the NFL buttonnfl_selector = "#global-nav-mobile > ul > li.active > ul > li:nth-child(2) > a > span.link-text"#find the NFL button and wait until presentnfl_button = WebDriverWait(driver, 10).until( EC.presence_of_element_located(( By.CSS_SELECTOR, nfl_selector )))#perform a chain of actions to click the elementactions\ .move_to_element(nfl_button)\ .click()\ .pause(4)\ .perform()#close the browserdriver.quit()This example is pretty much the same as the two previous with a few exceptions:
- We save the CSS selector of the "NFL" button
- We then find the button with
find_element() - We perform another
ActionChainthat:- Moves to the button with
move_to_element() clicks()on the elementpause()for 4 seconds so we can view the screen changing after we click
- Moves to the button with
Using Basic CSS Selectors
This section is devoted to showing off the flexibility of CSS selectors. There are code examples to find all sorts of elements on a page using different CSS criteria.
Find By ID
The ID attribute provides a unique identifier for an HTML element, making it a reliable and direct way to locate specific elements on a webpage.
As we have done previous examples, we can find an element by its ID using the # character.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find the username by IDusername = driver.find_element(By.CSS_SELECTOR, "#username")#type stuff in the boxusername.send_keys("some text")#close the browserdriver.quit()In the example above, we:
- Open Chrome and navigate to the site
- Find the username element using its CSS selector
- Type in the box with
send_keys() - Close the browser
Find By Class Name
The class name serves as an identifier for the element, allowing developers to apply consistent styling or behavior to multiple elements across a webpage.
This example performs the same task as the previous one, but we find the username element by its class name instead.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find the username by class nameusername = driver.find_element(By.CSS_SELECTOR, ".form-control")#type stuff in the boxusername.send_keys("some text")#close the browserdriver.quit()The only difference between this example and the previous one:
#usernamegets replaced by.form-control
Find By Tag Name
HTML elements are defined by tags, and each tag has a specific name that denotes the type of element it represents.
Now let's find the same element, but we'll find it using its tag name instead.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find the username by tagusername = driver.find_element(By.CSS_SELECTOR, "div > input")#type stuff in the boxusername.send_keys("some text")#close the browserdriver.quit()Using Attribute CSS Selectors
When using CSS selectors, we can also use the attributes of our element as criteria.
Attribute Presence
The example below finds all elements that contain an ID and then prints their ID to the console.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that contain an IDnew_list = driver.find_elements(By.CSS_SELECTOR, "[id]")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()Attribute Value
This example uses the previous example, but instead, we only search for elements where the ID is username.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that contain the ID, usernamenew_list = driver.find_elements(By.CSS_SELECTOR, "[id='username']")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()This approach allows for great flexibility in finding many items by changing a few simple variables or keywords. The only difference between this example and our previous one:
"[id]"gets replaced with"[id='username']"
Attribute Contains
We can also look for attributes that contain certain information by adding the * character.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that contain the ID, usernamenew_list = driver.find_elements(By.CSS_SELECTOR, "[id*='user']")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()In this example, we once again change on thing:
"[id='user']"becomes"[id*='user']"to search for elements that contain the string "user" in the ID
Attribute Starts With
We can use the ^ operator to select items that start with a specific string of text. Here we'll perform the same search, but instead find things that start with u.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that contain 'u' in the IDnew_list = driver.find_elements(By.CSS_SELECTOR, "[id^='u']")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()In this example, "[id*='user']" becomes "[id^='u']" to instead find elements where the id starts with "u".
Attribute Ends With
A simple change from the ^ operator to the $ operator can be used to specify attributes that end with a specific substring.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that end with 'e' in the IDnew_list = driver.find_elements(By.CSS_SELECTOR, "[id$='e']")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()The only change in this example:
"[id^='u']"is changed to"[id$='e']"
Combining CSS Selectors
We can also combine selectors easily in order to find certain elements. This greatly increases our ability to search for specific items and filter out extra nested elements that we don't need.
Descendant Selector
Here, we'll alter the example to find all input elements that are decendants of children of div.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all elements that end with 'e' in the IDnew_list = driver.find_elements(By.CSS_SELECTOR, "div input")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()Child Selector
To select direct child elements, we can use the > operator.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all input elements that are direct children of the div elementnew_list = driver.find_elements(By.CSS_SELECTOR, "div > input")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()Adjacent Sibling Selector
In this version of our example, we'll find all adjacent siblings of input elements. We'll replace > with +
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all adjacent siblingsnew_list = driver.find_elements(By.CSS_SELECTOR, "div + input")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()General Sibling Selector
To find all general siblings, we'll replace + with ~.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all direct siblingsnew_list = driver.find_elements(By.CSS_SELECTOR, "div ~ input")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()Pseudo-classes and Pseudo-elements (Limited Support)
Selenium has very limited support for finding pseudo-classes and pseudo-elements. It can be attempted with by combining selectors in the following way.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all first children of divnew_list = driver.find_elements(By.CSS_SELECTOR, "div:first-child")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()In this example, we use "div:first-child" in order to find all elements that are first children of div elements.
Combining Multiple Conditions
We can also combine multiple conditions to the search criteria for our page elements.
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")#find all text input elements of the class form-controlnew_list = driver.find_elements(By.CSS_SELECTOR, "input[type='text'].form-control")#print the id of each elementfor item in new_list: print(item.id)#close the browserdriver.quit()In the code above:
"input[type='text']"says that we want only input elements that take text.form-controladded to the end of our criteria says that we only want elements of the inputtype='text'that are also items with the class form-control
Debugging and Troubleshooting
Debugging and troubleshooting are crucial skills when working with Selenium and finding elements by CSS.
Here are some strategies to identify and resolve issues:
Inspecting Elements in Browser DevTools
Always inspect elements when first getting to know them, this way you can figure out exactly what you're looking for.
If you'd like to inspect an element, simply right-click on it to view information on it inside the console. While inspecting in the console, you should have a screen similar to the one below.
When inspecting an element, you can typically copy its CSS selector or its Xpath, both of which are great for scraping.
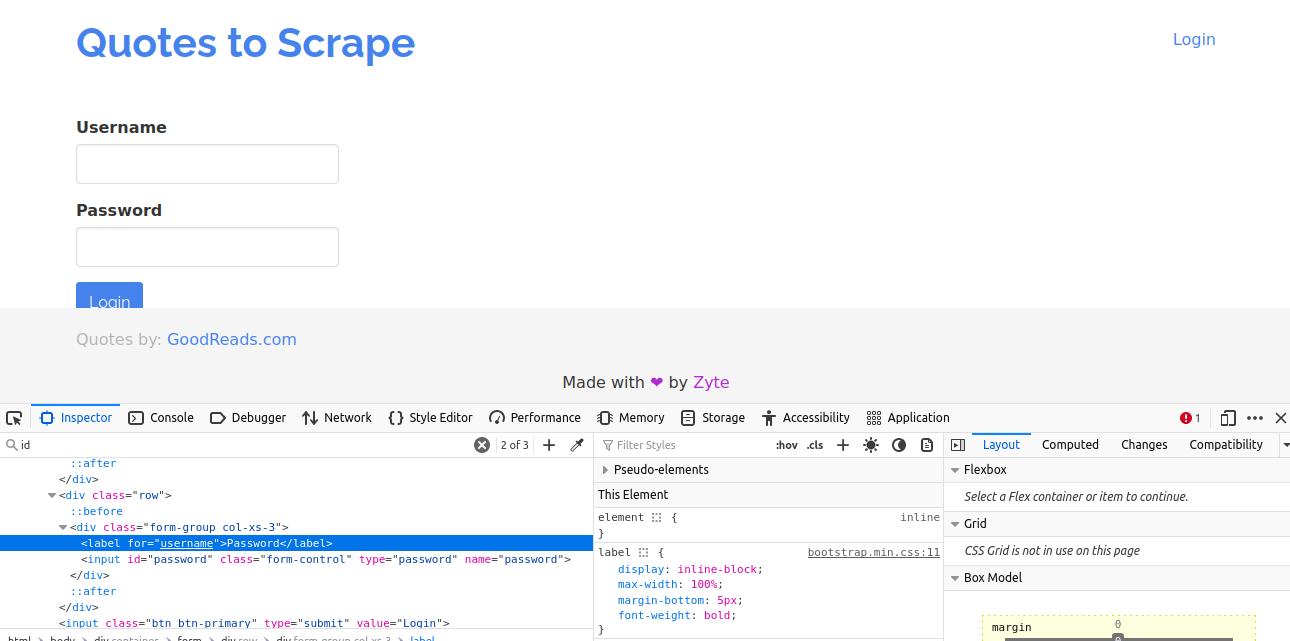 Inspect Quotes to Scrape page
Basic Waiting Strategies
When looking for elements, it is imperative to use waiting strategies in order to keep scripts executing as expected. We went over explicit waits in depth in an earlier section here.
Implicit waits are far simpler. We simply set them and forget them.
Take a look at the example below:
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom selenium.webdriver.common.action_chains import ActionChains#open Chromedriver = webdriver.Chrome()#set implicit waitdriver.implicitly_wait(10)#navigate to the sitedriver.get("https://espn.com")#id selector for the menu buttonselector = "#global-nav-mobile-trigger"#create an ActionChains objectactions = ActionChains(driver)#wait until the menu button appearsopen_menu = driver.find_element(By.CSS_SELECTOR, selector)#perform a chain of actionsactions\ .move_to_element(open_menu)\ .click()\ .perform()#close the browserdriver.quit()This example is largely the same as our explicit waits, with a few key differences:
- We do not use
ECorWebDriverWait - After creating a Chrome instance, we set up an implicit wait time of 10 seconds with
driver.implicitly_wait(10)
Remember, when waiting this way, the driver will wait implicitly for 10 seconds for any item to appear on the screen.
Error Handling
When writing code for any purpose (especially scraping), we're dealing with code that has a lot of moving and changing parts. A CSS class that was on the page yesterday might not be on the same page today. Error handling is an integral part of any scraper that with a long life.
The code below looks for a non-existent element on the screen. Pay attention to the keywords:
from selenium import webdriverfrom selenium.webdriver.common.by import By#open Chromedriver = webdriver.Chrome()#navigate to the sitedriver.get("https://quotes.toscrape.com/login")try: #find all elements that contain an ID small_header = driver.find_element(By.CSS_SELECTOR, "h6") #print the id of each element print(new_list)except: print("No h6 elements found!")finally: #close the browser driver.quit() print("successfully exited Selenium")In this code, we:
tryto find the non-existent element, without these keywords, the scraper would crash and exit right hereexceptto handle our exceptions, once the exception is thrown, we print a message to the screen and continue runtimefinallywe shutdown gracefully and tell the user that we exited successfully without a crash
Best Practices
Let's delve into the key practices that will ensure the reliability and maintainability of your scripts when working with CSS selectors.
Write Maintainable and Efficient Selectors
When writing selectors in Selenium, we should always write maintainable and efficient ones. It is very important that we use selectors we understand and comments when necessary.
Ideally, you should always be able to go back and change selectors in your code without a ton of overhead.
Find the Proper Balance Between Specific and Flexible Selectors
The web is constantly changing over time, your selectors will most likely break. When this happens you need to be able to change them easily so your code can evolve with the pages it scrapes.
Select the Most Appropriate CSS Selector for Different Scenarios
When creating your selectors, always make sure to inspect the page in order to find the proper CSS information and understand how the page is laid out. If your relevant information is all nested within a div which is nested inside of another div with a specific class, your code should reflect that.
This way, when something changes on the page (assuming the same basic layout is kept), your adjustments will be easy and minimal.
Optimize the Performance of Element Identification Using CSS selectors.
In order to keep your code as efficient as possible, you should only select necessary items on the page. Each element you select is another process running inside of Python and Python is resource intensive to begin with. When Python gets bogged down, it becomes exponentially slower.
Conclusion
Congrats! You've finished this tutorial. You can now atake this new knowledge and go apply it across the web. To learn more about Selenium or CSS Selectors check out the following links:
More Web Scraping Guides
If you liked this article and want to read more from ScrapeOps, take a look at these:
Then check out ScrapeOps, the complete toolkit for web scraping.