 ScrapeOps
How To Scroll Infinite Pages in Python
 Python Web Scraping Playbook13 min read
When web scraping, infinite scrollers can present some major challenges. Scraping is the easiest when we're dealing with static content. One of the best ways to deal with an infinite scroller is by using a headless browser such as Selenium, Playwright or Puppeteer.
In this article, we'll walk through the process of infinite scrolling with Selenium, and we'll attempt to scrape an infinite scroller with plain old Requests and also the ScrapeOps Headless Browser. When using Requests and BeautifulSoup, we have no support for JavaScript execution or dynamic content.
What is an Infinite Scroller?
An infinite scroller is a webpage where you can scroll infinitely.
How does that work?
When you visit a site and scroll to the bottom, the webpage automatically sends a request via JavaScript for more content.
Once it receives the content, the site then displays the new content in the form of HTML. When you reach the bottom again, a new request is once again sent and the content displayed. This process repeats on an infinite loop so you never run out of content to view.
When using an Infinite Scroller, we do not click a button for more content. As mentioned previously, the content is loaded dynamically when the user reaches the bottom of the page. Here's a detailed breakdown of the process:
- User goes to the site
- User scrolls to the bottom of the page
- The page (using JavaScript) realizes this when the user reaches the bottom
- The page (using JavaScript) sends a request to the website server for more content
- The page (using JavaScript) receives the response from the server
- Once it has the response, the page uses JavaScript to display the response as HTML on the site
Steps 2 through 6 will literally repeat forever!!!
This is vastly different from traditional pagination. With traditional pagination, the user reaches the bottom of the page and clicks a "next" button which fetches the next page.
Traditional pages are far easier to scrape because we're dealing with fixed data. With fixed data, we actually get a structure we can follow in order to create our requests and plan out our actions on the page.
With an infinite scroller, it is far more difficult because you can't simply go to the next page...all the content is loaded on the existing page dynamically.
This makes our data far more difficult to predict and therefore scrape.
Challenges in Scraping Infinite Scroll Pages
Infinite Scrollers are far more unpredictable and unstructured in comparison to normal paginated websites. Infinite scroll pages pose several challenges for web scraping:
-
Dynamic Content: Traditional web scraping techniques rely on parsing the static HTML content of a page, so dynamically loaded content may not be accessible to these methods.
-
Incomplete Initial Response: The initial HTML response obtained by the scraper does not contain all the data available on the page, making it challenging to extract a comprehensive dataset.
-
Asynchronous Loading: Content on infinite scroll pages is often loaded asynchronously, meaning that multiple requests may be sent to the server in the background as the user scrolls. Traditional web scraping techniques, which operate on a single request-response cycle, may not capture these asynchronous requests and the data they fetch.
-
Dynamic Selectors: Elements on infinite scroll pages may have dynamically generated IDs or classes, making it difficult to reliably locate and extract data using static CSS selectors or XPath expressions.
-
Rate Limiting and Throttling: As infinite scroll pages require multiple requests to load additional content, they may trigger rate limiting or throttling mechanisms mechanisms more frequently, increasing the risk of being blocked by the website.
Limitations of Traditional HTTP Clients in Handling Infinite Scroll
Traditional HTTP clients face several limitations when it comes to handling infinite scroll pages:
-
Single Request-Response Cycle: Traditional HTTP clients operate on a single request-response cycle. They do not handle subsequent requests triggered by user interactions, such as scrolling, that dynamically load additional content.
-
Inability to Execute JavaScript: Traditional HTTP clients do not execute JavaScript, which is often responsible for triggering the loading of additional content in infinite scroll pages.
-
Limited Interaction: HTTP clients lack the ability to interact with a webpage like a human user would which are often necessary to trigger the loading of additional content in infinite scroll pages.
-
Partial Data Retrieval: Since traditional HTTP clients only retrieve the initial HTML content of a webpage, they may miss out on dynamically loaded data that appears below the initially visible content.
-
Static Parsing: Traditional HTTP clients typically rely on static parsing techniques to extract data from HTML content.
-
Rate Limiting and Throttling: Sending a large number of requests to fetch dynamically loaded content from infinite scroll pages can trigger rate limiting or throttling mechanisms implemented by websites to prevent excessive scraping activity.
Not even the Requests and BeautifulSoup stack is built properly to handle infinite scrolling. When using a headless browser, we actually get JavaScript support so we can load this dynamic content.
This makes a headless browser like Selenium a perfect choice for scraping an infinite scroller.
Scrolling Infinite Pages in Python
To scroll infinite pages in Python, you can use various methods depending on the environment and tools you are working with. Here are explanations of a few methods:
Method 1: Scrolling Infinitely with Selenium
Selenium is a package for browser automation. More specifically, Selenium is also great when you run it as a headless browser.
For those of you who are unfamiliar, a headless browser is a browser without a GUI (graphical user interface). When we run in headless mode, we save resources because we don't have the overhead of running a GUI, but we still get the benefits of a fully functional browser.
To scrape an infinite scroller with Selenium, our strategy is actually very simple.
Our strategy can be laid out like this:
- Launch the browser
- Go to the site
- Scroll to the bottom
- Take a screenshot
- Wait for new content
- Repeat steps 3 through 5 until we have our desired data
Here is a Python script that does exactly this. While this script is made to stop after 5 screenshots, but you could change the number however you want, you could even use while True to leave it running on a forever loop.
from selenium import webdriverfrom time import sleep#create a custom options instanceoptions = webdriver.ChromeOptions()#add the headless arg to our optionsoptions.add_argument("--headless")#launch a browser with our custom optionsdriver = webdriver.Chrome(options=options)#go to the sitedriver.get("https://quotes.toscrape.com/scroll")#we wish to repeat this process 5 timesfor i in range(0, 5): #use JavaScript to scroll to the bottom of the page driver.execute_script("window.scrollTo(0, document.body.scrollHeight)") #take a screenshot driver.save_screenshot(f"selenium-shot{i}.png") #sleep for a fifth of a second sleep(0.2)#we've taken our 5 screenshots, close the browser gracefullydriver.quit()In the example above, we:
- Create a custom instance of
ChromeOptions() - Add the
"--headless"argument to our options - Launch the browser with our custom options,
webdriver.Chrome(options=options) - Go to the site
- Create a
forloop that executes 5 times:- Use JavaScript to efficiently scroll to the bottom of the page
driver.execute_script("window.scrollTo(0, document.body.scrollHeight)") - Take a screenshot with a unique number,
driver.save_screenshot(f"selenium-shot{i}.png") - Wait a fifth of a second for content to load
- Use JavaScript to efficiently scroll to the bottom of the page
Traditionally, when waiting for an element to load, we would use its locator and wait until it is present. Because we're on an infinite scroller, we don't know exactly what data to expect next.
With Puppeteer or Playwright, we could use waitUntil: "networkidle", which waits until there are no requests going to or from the page. Selenium does not support this, so after several runs, I noticed that 0.1 was too short of a wait, and 1 second was far too long so I went with 0.2.
Here are the screenshots:
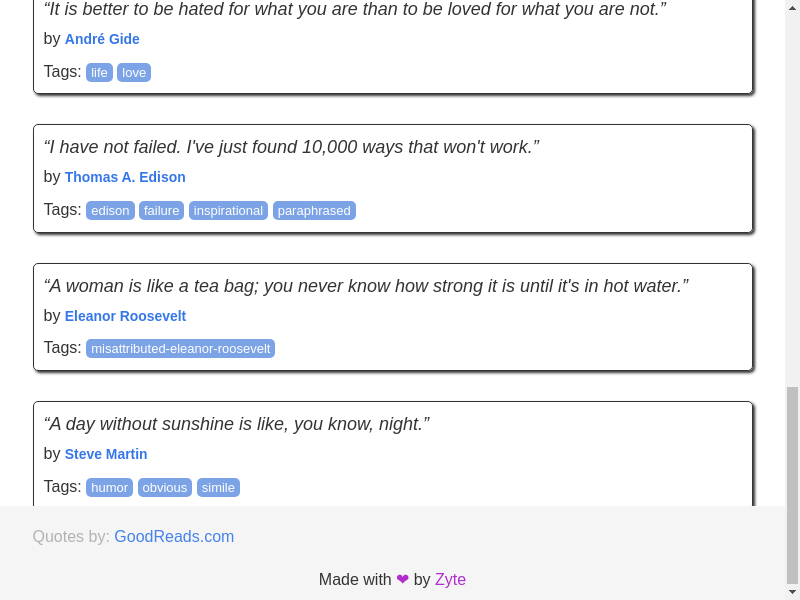 Selenium Quotes to Scrape Beginning
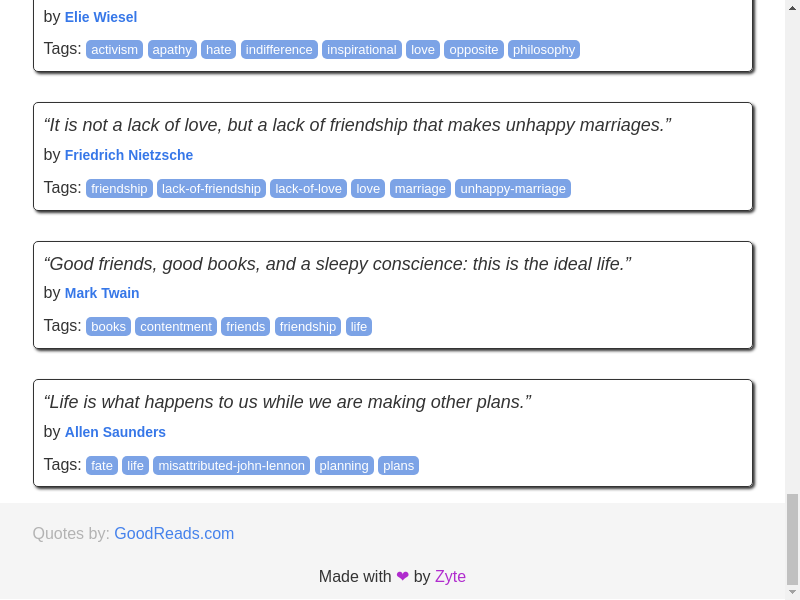 Selenium Quotes to Scrape First Scroll
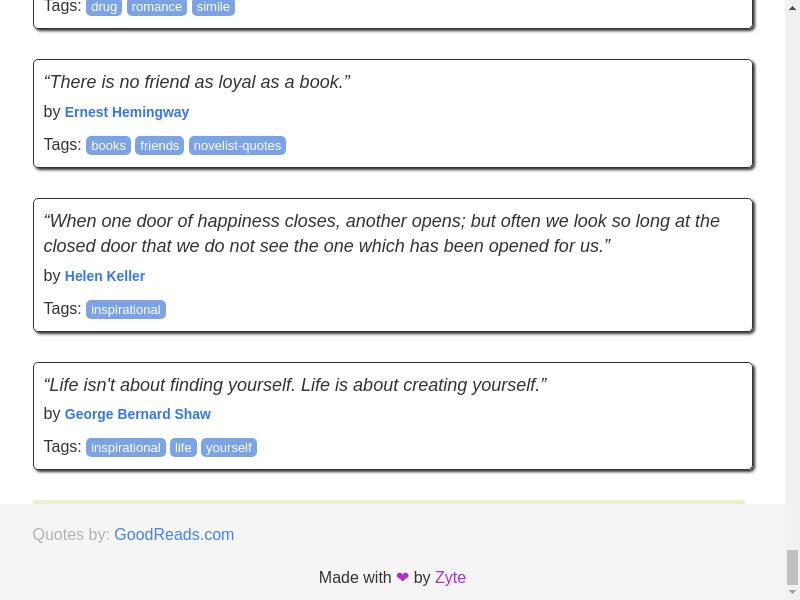 Selenium Quotes to Scrape Second Scroll
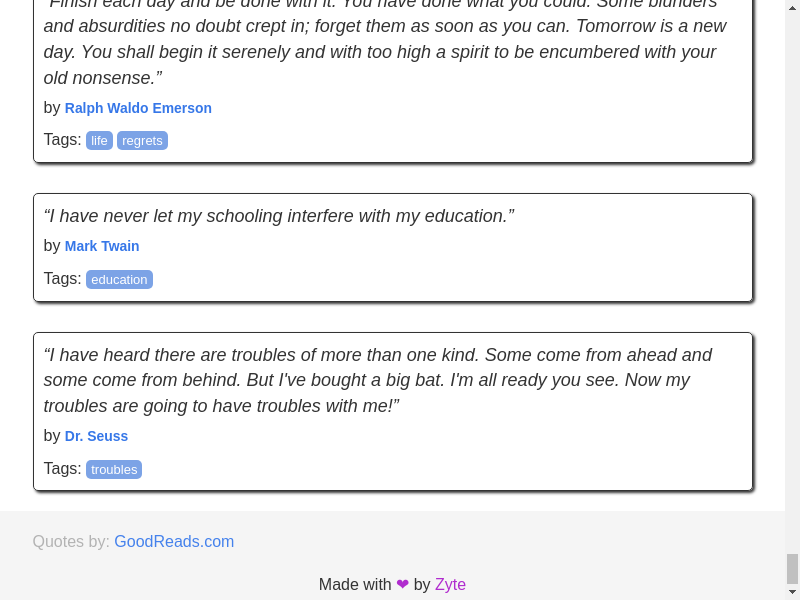 Selenium Quotes to Scrape Third Scroll
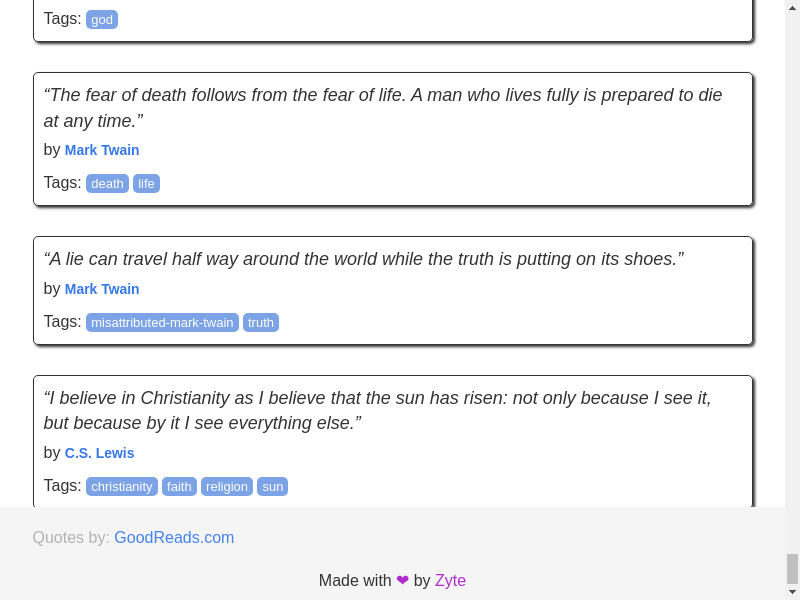 Selenium Quotes to Scrape Fourth Scroll
As you have probably noticed, the final two shots are the same. This is because https://quotes.toscrape.com/scroll actually has a reachable end of the page where we stop getting new content.
When scraping a real infinite scroller, this doesn't happen.
Method 2: Simulate Background API Requests
Simulating background API requests is another approach to handle infinite scroll pages, especially when the website dynamically loads content using AJAX or similar techniques.
This method involves inspecting the network traffic in the browser's developer tools to identify the API endpoints responsible for fetching additional content.
Step 1: To Capture Requests Using DevTools
If you open the developer console within your browser, as you probably already know, you can inspect the page. If you look at the additional options in the console, there is also a tab to view Network activity.
- Right click your page
- Click
inspect - Select the
Networktab - Choose the
XHRfilter
When you are finished, you should see a result similar to the picture below. As you can see, the Network tab is highlighted in blue and XHR is selected from the options on the right above the console.
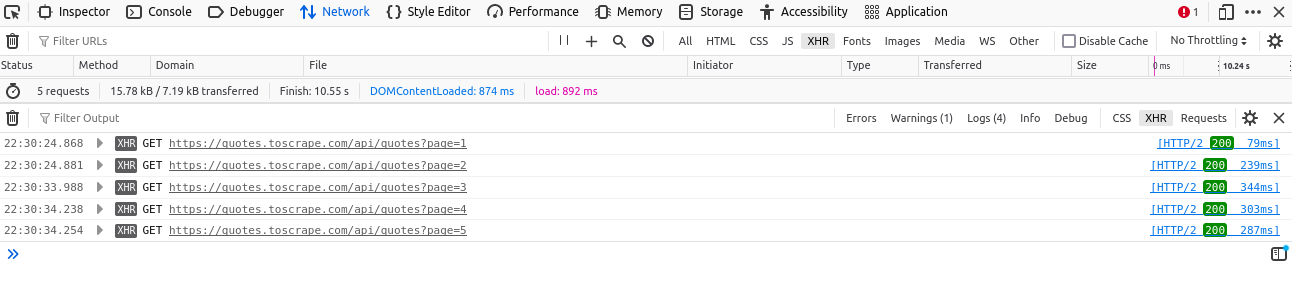 Inspect Captured Requests
As you can see, the basic request used is GET https://quotes.toscrape.com/api/quotes?page={page_number}. This is repeated for pages 1 through 5.
Let's use Requests to fetch this information.
Step 2: Simulating Scrolling With Requests
When we're scrolling and we reach the bottom of the page, the site actually just requests some data from the server and displays it to us as HTML.
Here's some Python code to fetch these GET requests we captured earlier and take a screenshot. Our "scrolling" algorithm is really simple.
We want 5 pages, so our strategy is outlined below.
- Create a base page number
- Create a loop to repeat the process five times
- While we're in the loop:
- fetch the api response
- take a screenshot of the result
- increment the page number
import requestsimport imgkit#default page numberpage_number = 1#do the following 5 timesfor i in range(0, 5): #url with the page number url = f"https://quotes.toscrape.com/api/quotes?page={page_number}" #get the url data = requests.get(url) #take a screenshot of the result imgkit.from_string(data.text, f"requests-quotes{i}.png") #increment the page number page_number += 1 In this code example, we:
- Create a variable,
page_numberto be used specifically for fetching and naming purposes - Create a
forloop that runs 5 times - From within our
forloop, we:requests.get()the information with ourpage_number- Take a screenshot of our result
- Increment
page_number
Here are the screenshots, for those of you unfamiliar with how API endpoints work, this might come as a bit of a surprise.
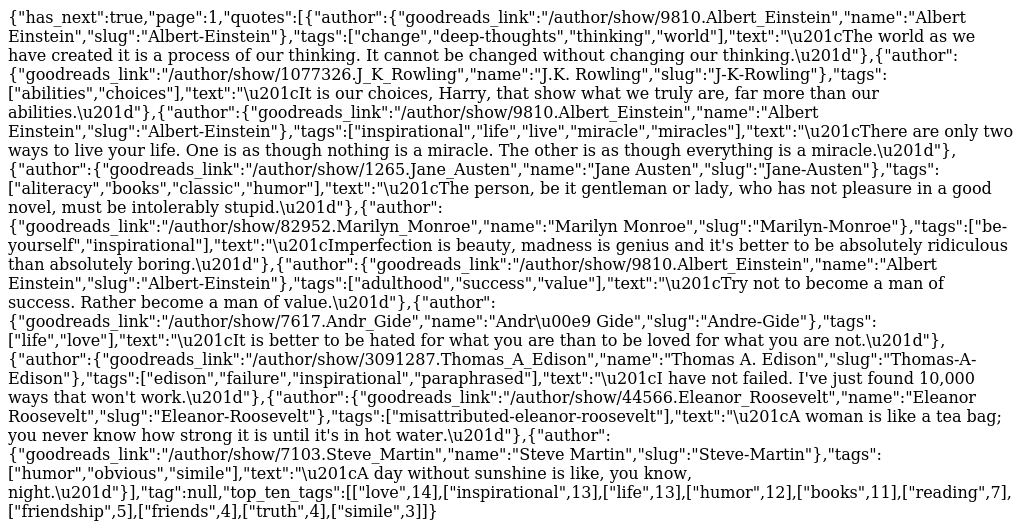 Requests Quotes to Scrape Beginning
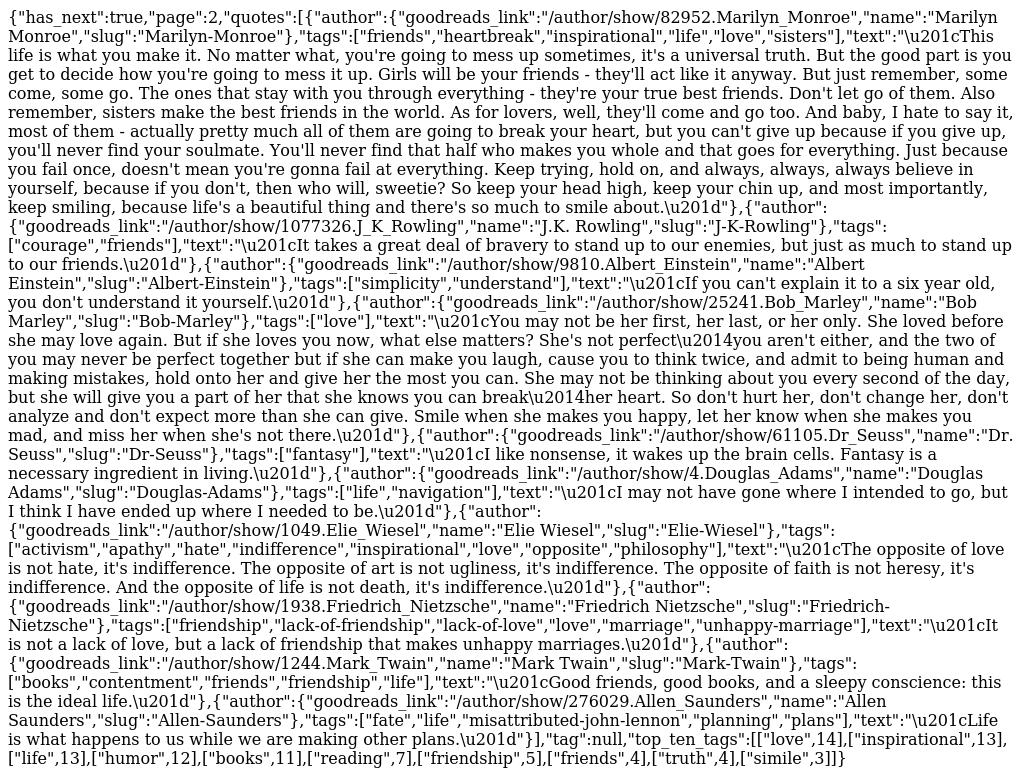 Requests Quotes to Scrape First Scroll
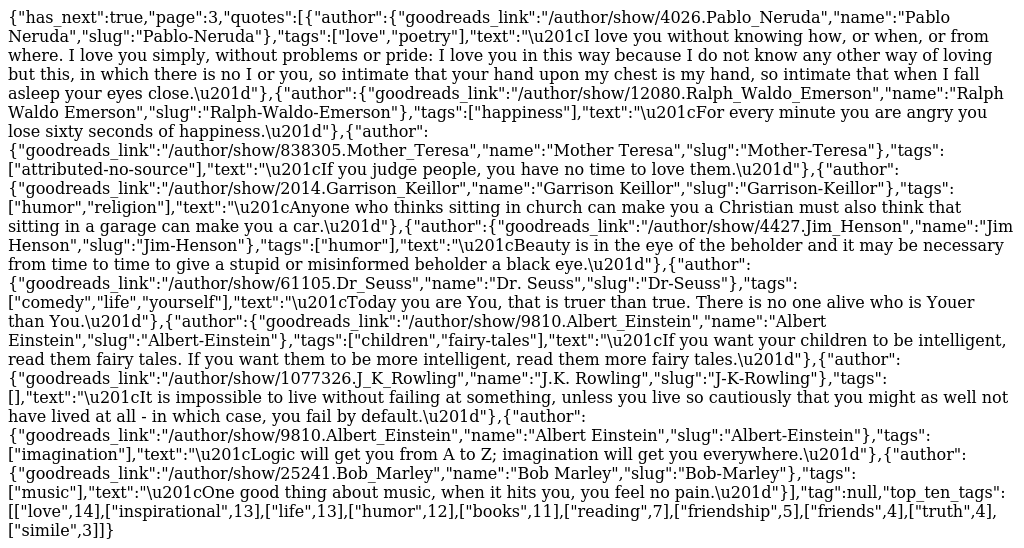 Requests Quotes to Scrape Second Scroll
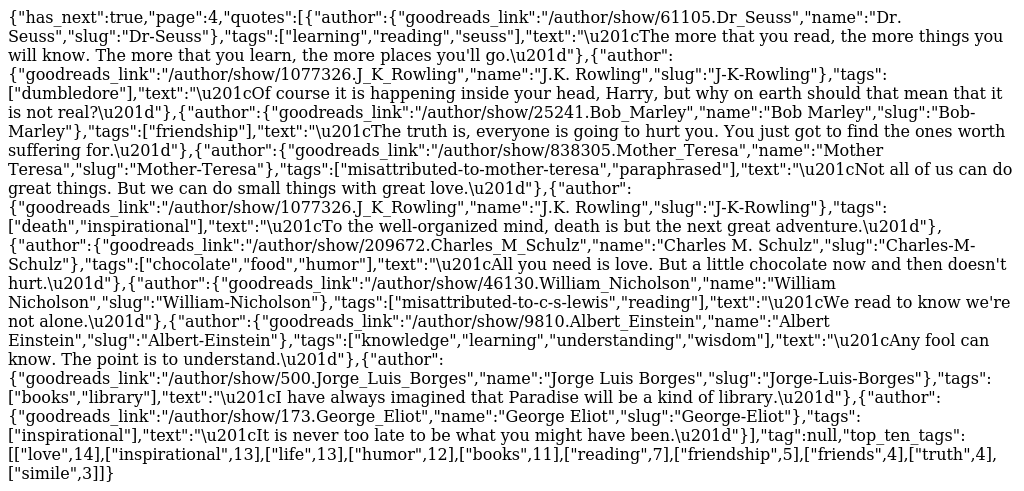 Requests Quotes to Scrape Third Scroll
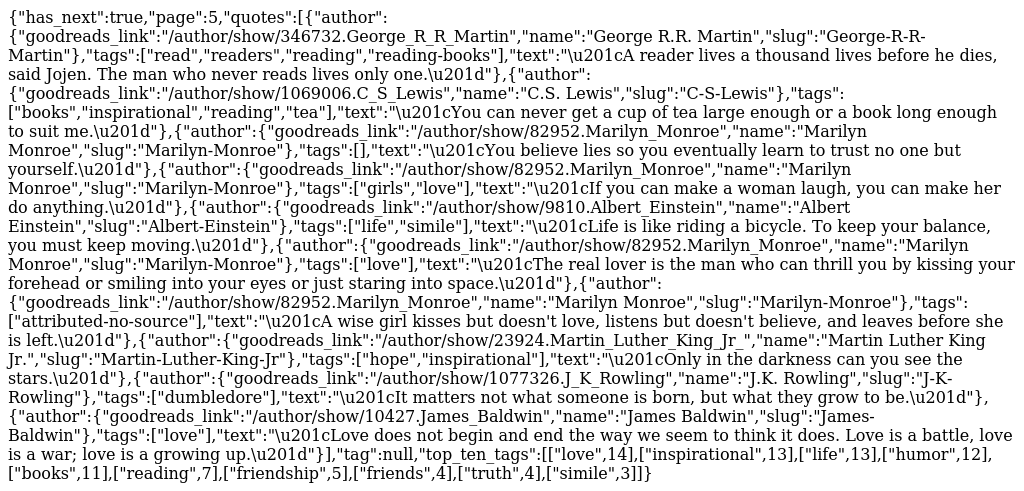 Requests Quotes to Scrape Fourth Scroll
We don't receive any HTML content whatsoever. All of our responses come in the form of JSON.
Even with BeautifulSoup, this is rather useless as far as screenshots go. However, if you know how to properly index JSON in Python, we can use this method to retrieve a ton of data in a very fast and efficient manner.
All in all, while this method does retrieve data very efficiently, our inability to render content means that we'd need an alternative method to clean and save our data.
In practice, we would parse all this information and usually save it as a spreadsheet file or insert it into a database somewhere.
Method 3: Simulate Scrolling With Requests and ScrapeOps Headless Browser
This final method is actually something of a happy medium between our first two methods. The ScrapeOps API actually comes with a headless browser right out of the box.
It doesn't have quite all the bells and whistles that we get with Selenium, but it should give us the actual page when we scroll and load new content.
It is still very new and under heavy development, in fact we are only on ScrapeOps V1 at the current moment.
Here is the code to interact with the ScrapeOps browser. As you can see, we pass a list of instructions for the browser to execute. It should execute the list and return our response.
import requestsfrom bs4 import BeautifulSoupfrom urllib.parse import urlencodeimport imgkit#url of our proxy serverproxy_url = "https://proxy.scrapeops.io/v1/"#url of the page we want to scrapetarget_url = "https://quotes.toscrape.com/scroll"#amount to scroll byscroll_amount = 5000params = { #your scrapeops api key "api_key": "YOUR-SUPER-SECRET-API-KEY", #url we'd like to go to "url": target_url, #we DO want to render JavaScript "render_js": True, #a list of instructions to execute on the page "instructions": [ #scroll down by our scroll amount {"scroll_y": scroll_amount}, #wait 5 seconds for content to load {"wait": 5000} ] }#repeat the following process 5 timesfor i in range(0, 5): #send the request to proxy server response = requests.get(proxy_url, params=params, timeout=120) #create a BeautifulSoup instance soup = BeautifulSoup(response.text, "html.parser") #remove the JavaScript so BeautifulSoup can parse the page for script in soup(["script", "link", "img"]): script.decompose() clean_html = str(soup) #use imgkit to convert the html to a png file imgkit.from_string(clean_html, f"scrapeops-quotes{i}.png") #add another scroll to the instructions list params["instructions"].append({"scroll_y": scroll_amount}) #add another 5 second wait to the instructions list params["instructions"].append({"wait": 5000})There is a ton going on here. In this code, we:
- Create a
proxy_urlvariable which holds the url of the ScrapeOps API target_urlholds the url of the site we'd like to scrapescroll_amountis the amount we want to scroll each time we scrollparamsholds all of the parameters we'd like to pass on to the server- The
"instructions"field ofparamsholds a list of the things we want the server to do - Once we enter our 5 time loop, we:
- send a request to the server with our custom
params - Use
BeautifulSoupto remove the JavaScript from our response - Take a screenshot with
imgkit - Add another
"scroll_y": scroll_amountso we scroll down one more time than the previous try - Add another
"wait": 5000to the end of our list so we can wait 5 more seconds for the content to appear from our new scroll
- send a request to the server with our custom
Here are the results:
 ScrapeOps Quotes to Scrape Beginning
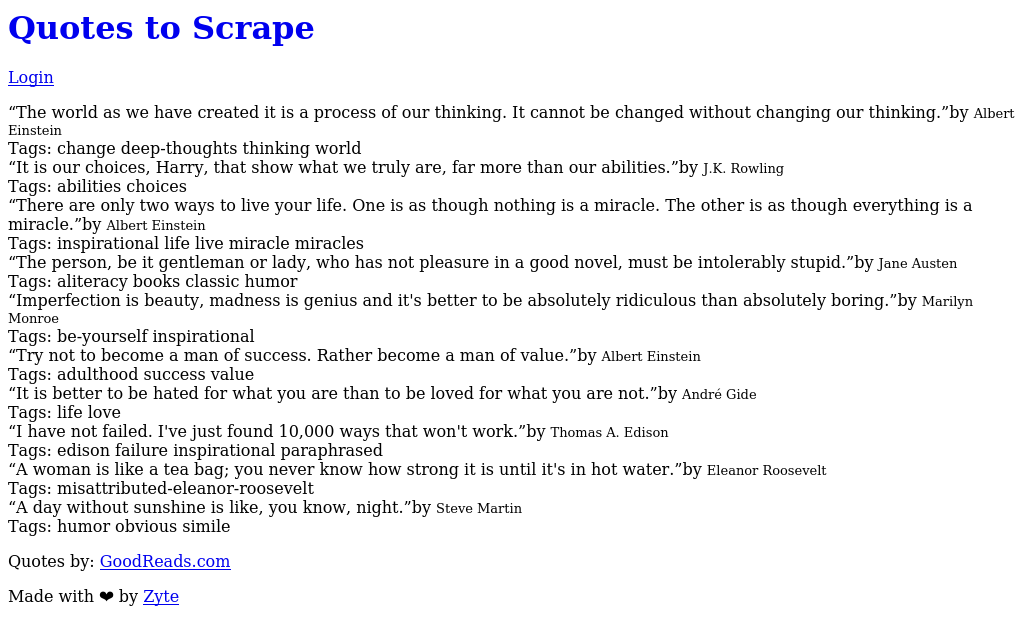 ScrapeOps Quotes to Scrape First Scroll
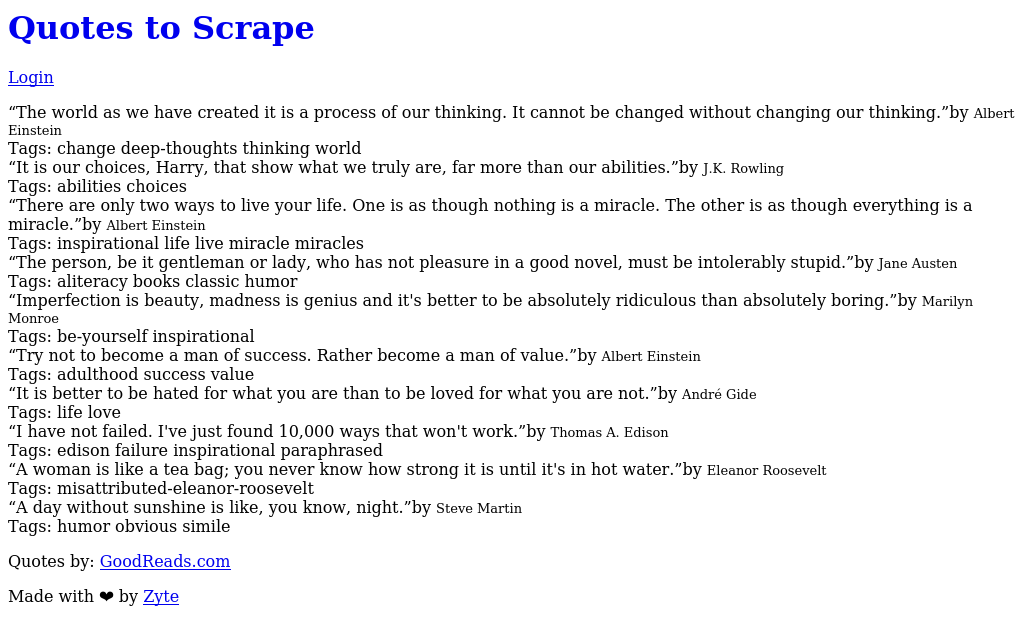 ScrapeOps Quotes to Scrape Second Scroll
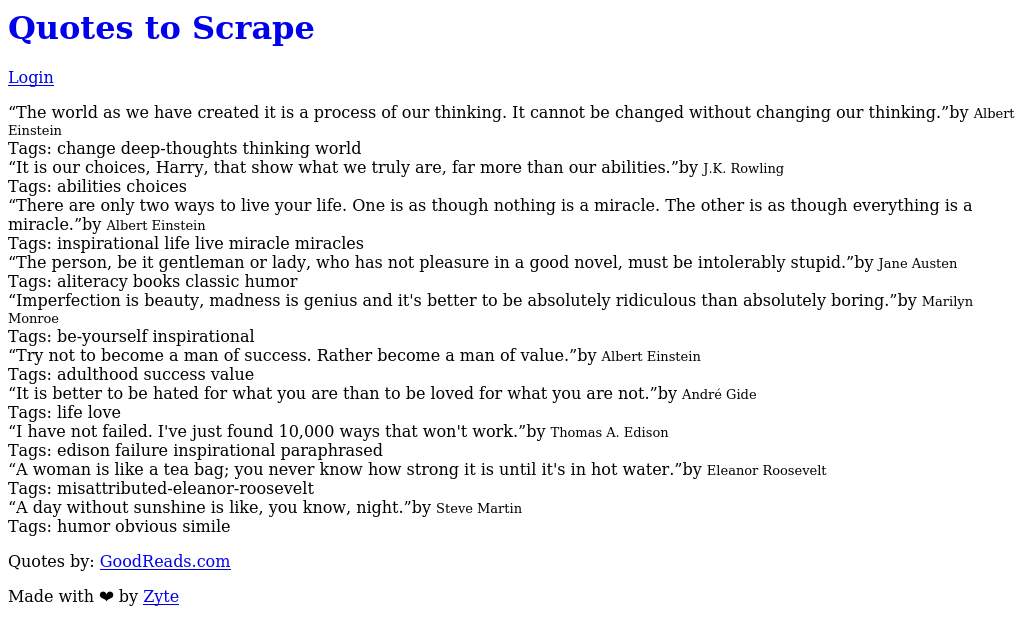 ScrapeOps Quotes to Scrape Third Scroll
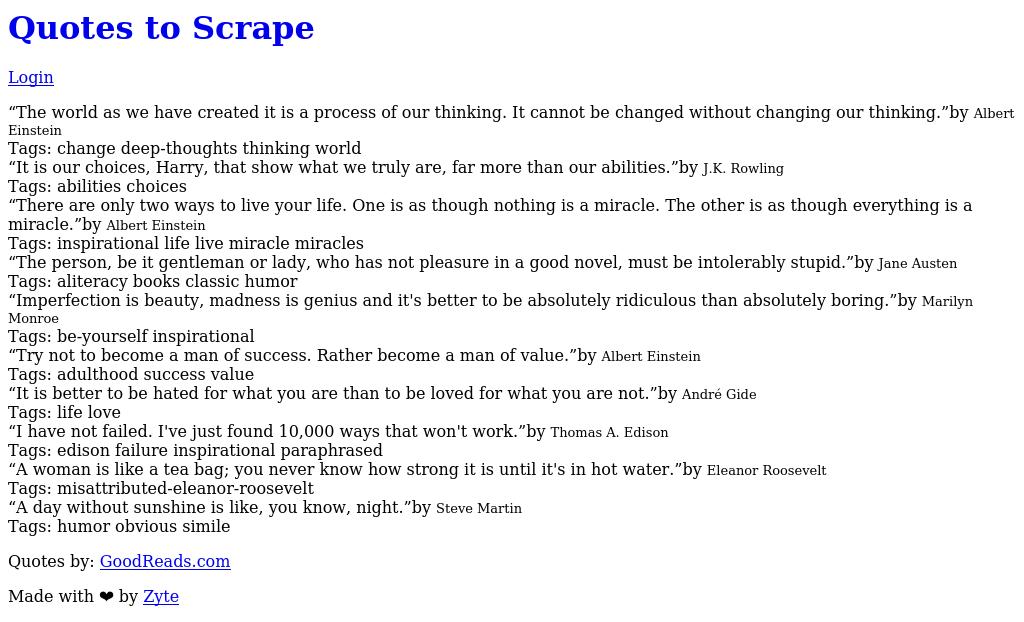 ScrapeOps Quotes to Scrape Fourth Scroll
As you can see in the results above, even though we're adding additional scrolls and waits to our list of instructions, we wind up with the same screenshot each time.
The ScrapeOps API is still under heavy development and in time, I'm sure this will be resolved.
Case Study: Scrape Behance for Infinite Scrolling
Behance is an online platform and social media network where creative professionals can showcase their work, discover inspiring projects, and connect with other creatives worldwide.
This platform is a great example for this case study since it has an infinite scrolling page.
Scraping Behance With Selenium
Let's take our Selenium example and tweak it to work with Behance.
The only difference between this example and the Selenium quotes example is the URL.
Here is the code:
from selenium import webdriverfrom time import sleep#create a custom options instanceoptions = webdriver.ChromeOptions()#add the headless arg to our optionsoptions.add_argument("--headless")#launch a browser with our custom optionsdriver = webdriver.Chrome(options=options)#go to the sitedriver.get("https://www.behance.net/galleries?tracking_source=nav20")#we wish to repeat this process 5 timesfor i in range(0, 5): #use JavaScript to scroll to the bottom of the page driver.execute_script("window.scrollTo(0, document.body.scrollHeight)") #take a screenshot driver.save_screenshot(f"selenium-behance{i}.png") #sleep for a fifth of a second sleep(0.25)#we've taken our 5 screenshots, close the browser gracefullydriver.quit()Here are the results:
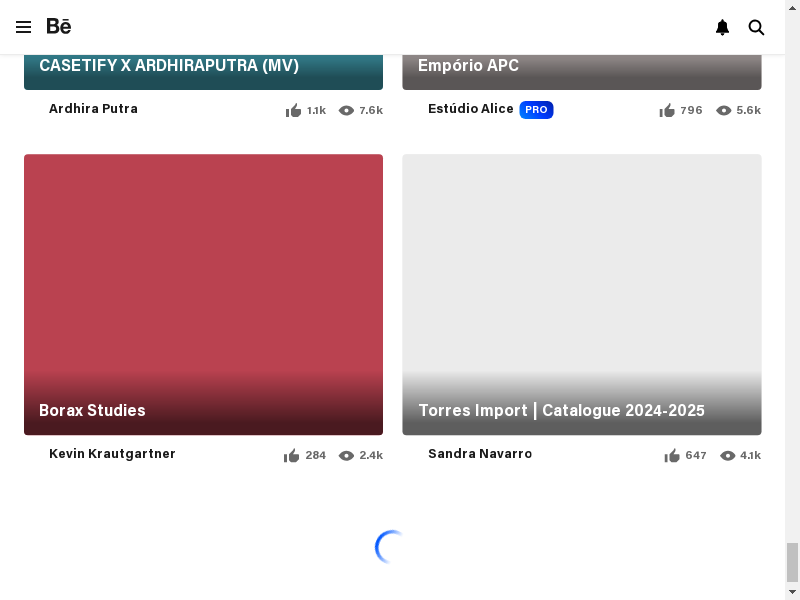 Selenium Behance Beginning
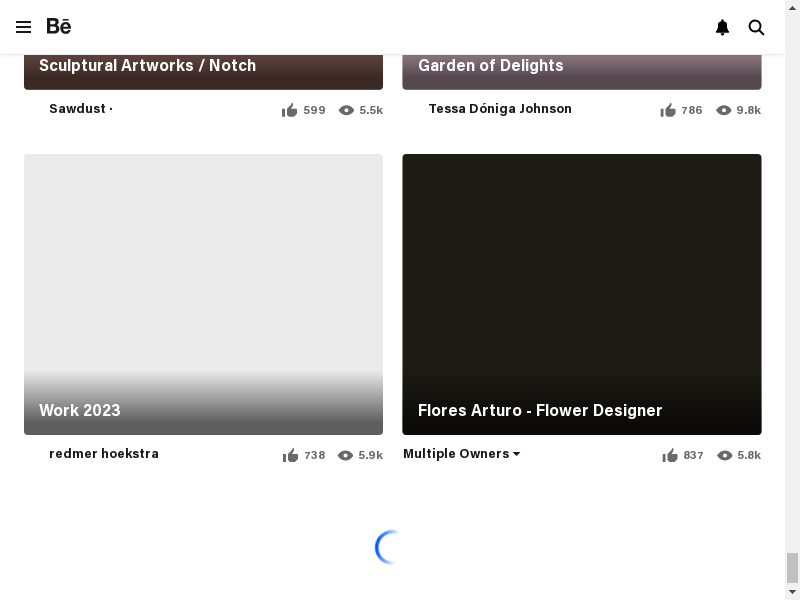 Selenium Behance First Scroll
 Selenium Behance Second Scroll
 Selenium Behance Third Scroll
 Selenium Behance Fourth Scroll
As you can see, in shot 4, we reached the actual bottom of the page, so once again we have a duplicate.
Scraping Behance With Requests
As you probably noticed, with Selenium, we were able to receive the actual page, many of the images were either still loading or only partially loaded.
Let's use DevTools to see what some of these images actually are.
Here is a screenshot of Behance's network requests in DevTools.
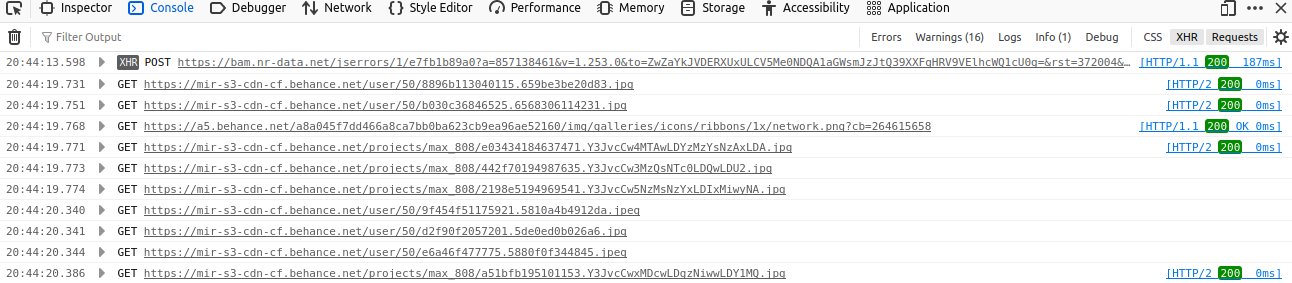 Behance.net Network Requests
As you can see, there are a bunch of GET requests for different images. With this method, we can't directly scrape the page, but we can scrape all of these images very quickly and with relative ease.
This script is going to be quite a bit different from our first one. Instead of taking a screenshot of the page, our goal will be to fetch and download these images with Requests.
import requests#list of image urlsurls = [ "https://mir-s3-cdn-cf.behance.net/user/50/8896b113040115.659be3be20d83.jpg", "https://mir-s3-cdn-cf.behance.net/user/50/b030c36846525.6568306114231.jpg", "https://mir-s3-cdn-cf.behance.net/projects/max_808/e03434184637471.Y3JvcCw4MTAwLDYzMzYsNzAxLDA.jpg", "https://mir-s3-cdn-cf.behance.net/projects/max_808/442f70194987635.Y3JvcCw3MzQsNTc0LDQwLDU2.jpg", "https://mir-s3-cdn-cf.behance.net/projects/max_808/2198e5194969541.Y3JvcCw5NzMsNzYxLDIxMiwyNA.jpg"]#counter variable for our file namescounter = 0#iterate through the urlsfor url in urls: #get each url response = requests.get(url) #write the binary to a png file with open(f"requests-behance{counter}.png", "wb") as file: file.write(response.content) #increment the counter counter += 1In this example, we:
- Create a list,
urlswhich holds the urls of the images fetched by Behance - Create a
countervariable starting at 0, this is used strictly for naming our files. requests.get(url)to fetch each image:with open(f"requests-behance{counter}.png", "wb") as file:opens a png file with the counter number and gives us the permission to write binaryfile.write(response.content)writes the actual binary of the image to the file- We then increment the counter
Here are the results of this method:
 Behance Profile Photo
 Behance Profile Photo 2
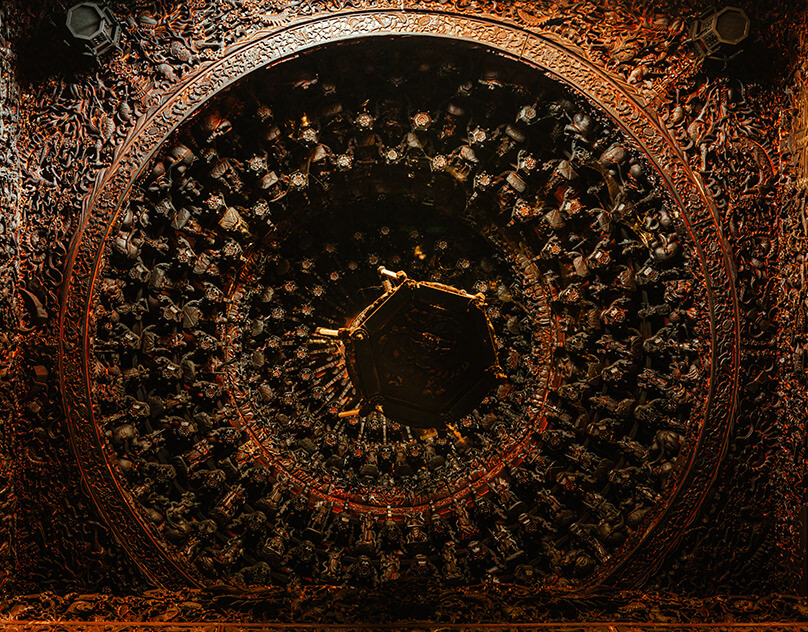 Behance art
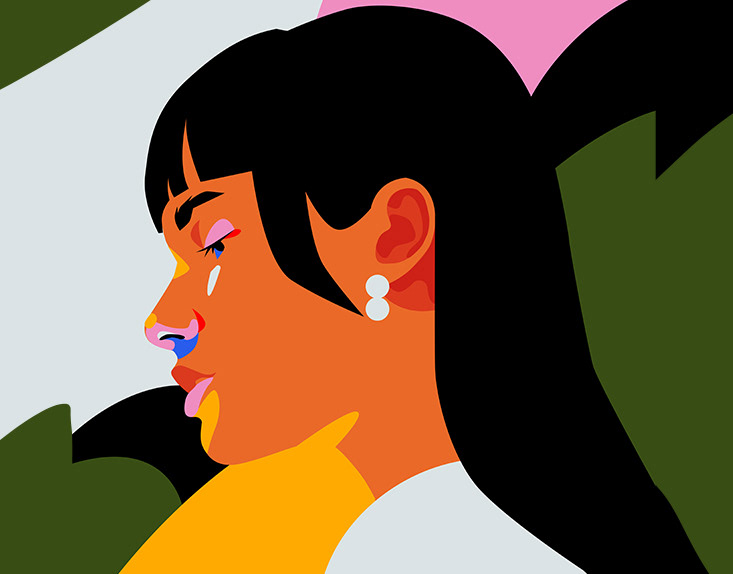 Behance art 2
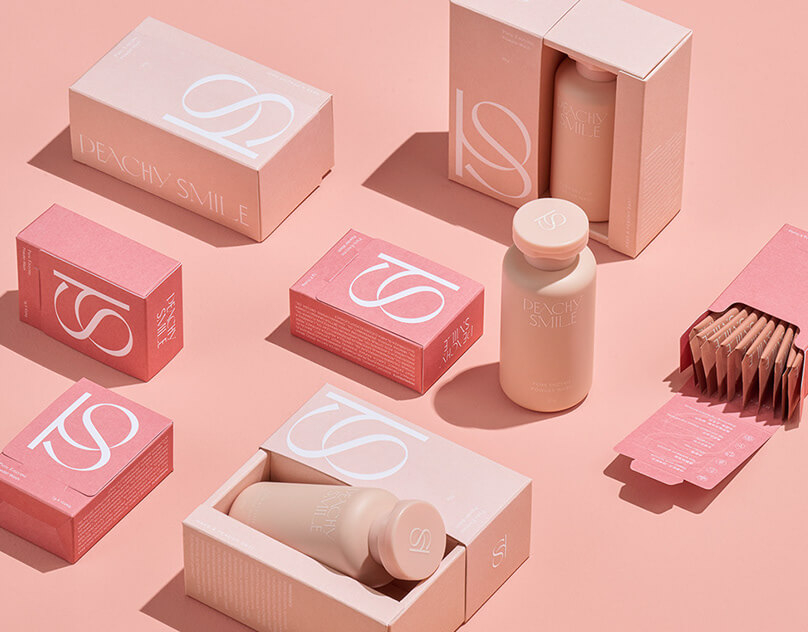 Behance art 3
As you can see from the images, even though we didn't get the full page, if we know the URLs of the images we need, this method can be super effective. We didn't need to wait for dynamic content, we fetched it all on our own and downloaded the images. Scraping this way can be far more targeted and resource efficient.
Scraping Behance With ScrapeOps Headless Browser
While the results weren't exactly fruitful from our quotes example, we went ahead and tested the ScrapeOps Browser on Behance as well.
Similar to the Selenium example, all that's been changed is the url. Here is the code:
import requestsfrom bs4 import BeautifulSoupfrom urllib.parse import urlencodeimport imgkit#url of our proxy serverproxy_url = "https://proxy.scrapeops.io/v1/"#url of the page we want to scrapetarget_url = "https://www.behance.net/galleries?tracking_source=nav20"#amount to scroll byscroll_amount = 5000params = { #your scrapeops api key "api_key": "YOUR-SUPER-SECRET-API-KEY", #url we'd like to go to "url": target_url, #we DO want to render JavaScript "render_js": True, #a list of instructions to execute on the page "instructions": [ #scroll down by our scroll amount {"scroll_y": scroll_amount}, #wait 5 seconds for content to load {"wait": 5000} ] }#repeat the following process 5 timesfor i in range(0, 5): #params to authenticate and tell the browser what to do #send the request to proxy server response = requests.get(proxy_url, params=params, timeout=120) #create a BeautifulSoup instance soup = BeautifulSoup(response.text, "html.parser") #remove the JavaScript so BeautifulSoup can parse the page for script in soup(["script", "link", "img"]): script.decompose() clean_html = str(soup) #use imgkit to convert the html to a png file imgkit.from_string(clean_html, f"scrapeops-behance{i}.png") #add another scroll to the instructions list params["instructions"].append({"scroll_y": scroll_amount}) #add another 5 second wait to the instructions list params["instructions"].append({"wait": 5000})While somewhat disappointing, below are the results from the ScrapeOps browser. As you can see, they are all blank.
 ScrapeOps Behance Beginning
 ScrapeOps Behance First Scroll
 ScrapeOps Behance Second Scroll
 ScrapeOps Behance Third Scroll
 ScrapeOps Behance Fourth Scroll
Conclusion
This experiment was quite enlightening. We learned that Selenium is by far the best option when we actually want to wait for dynamic content to load.
When using a combination of Requests and the DevTools console, we can perform extremely targeted scrapes for specific API data and images.
Finally, while ScrapeOps offers an excellent proxy API, the headless browser still has quite a way to go.
There is an appropriate choice for every tool and you should always use the correct tool for the job.
- Selenium for dynamic content
- Requests for targeted content and API calls
- ScrapeOps for a proxy service...and a headless browser alternative in the future!
If you'd like to know more about any of the tools or frameworks used in this article, you can find their documentation here:
More Python Web Scraping Guides
Now that you've gotten your feet wet with each of these tools, go build something! If you're in the mood to binge read, take a look at these articles:
Then check out ScrapeOps, the complete toolkit for web scraping.